Tools Bench.

Product launches and open-source repos with enough signal to earn a second look.

Last Brew Time: Sep 13, 2026, 10:51 AM PT

Insight

The open video-model ecosystem has hit a point where speed hacks need their own referee

Featured

HF Spaces510 likes

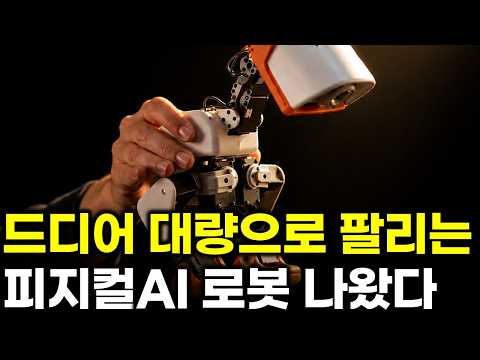
Real trained RL policies for the Microduck robot, running fully in the browser: MuJoCo compiled to WebAssembly steps the physics, onnxruntime-web runs the policy network at 50 Hz. No server, no backend. Two locomotion variants of the same robot are included: legs (walking, the default) and rollers (the wheeled skating variant). Press M (or hold D-pad up ~1 s on a gamepad) to switch; the roller model, meshes and policies are lazy-loaded on the first switch. | Mode | Checkpoint | What it does | |--------|-----------|--------------| | Run (legs) | BESTalphawalking.onnx | Velocity-tracking locomotion (arrows / WASD to steer) | | Sit | BESTalphasitstand.onnx | Sits down on its hull, stands back u...
Market Signal

Why It Has Market Pull

Officially published by a Hugging Face-owned robotics company, this browser sandbox runs the real trained walking and skating policies for a $399 open-source robot via physics-in-WebAssembly and an ONNX runtime in the browser, and has already spawned independent community forks.

  • 510 Hugging Face likes, last updated just days before this evaluation
  • Published under the official robotics-company org, the maker of a well-known open-source robotics platform
  • Tied to a real $399 hardware preorder covered by Engadget, MarkTechPost, and Interesting Engineering
  • Eight community discussion threads, including a full community fork that a team member praised directly
  • Runs genuine reinforcement-learning policies client-side via an ONNX web runtime plus a physics-to-WebAssembly build — a real sim-to-real workflow, not a rebranded demo

feedbacks

What People Are Saying

  • "this is really cool, love the living room circuit and the bring-your-own-policy angle. we will take a closer look on our side, nice work!"HF Space discussion

  • "Modified version of the simulator for competitive skating policy racing... multiple ducks racing around"HF Space discussion

  • "boot failed SyntaxError: Unexpected token 'v'... in the 3D model loader"HF Space discussion

  • "I've been experimenting with an optional adapter that lets a script drive the browser simulator using the physical duck's JSON-RPC API."HF Space discussion

  • "Hugging Face and the robotics company open pre-orders for the $399 Microduck"Engadget headline

  • "Tiny open-source robot duck can walk and learn from its mistakes"Interesting Engineering headline
HF Spaces429 likes

Video generation with a synchronized soundtrack MiniMax-H3 — unquantized, split across two Spaces Joint video and soundtrack out of a single denoising pass, at bfloat16 with no quantization anywhere. This Space is the denoising half: the 61.73 GiB transformer and the two autoencoders. The 62.14 GiB Qwen3-VL conditioner runs in qwen3vl-conditioner, which this Space calls over the gradio API for every request. The weights are the public MiniMaxAI/MiniMax-H3 diffusers checkpoint. MiniMax-H3 is 195.9 GiB in bfloat16 and a ZeroGPU Space is evicted at 150 GB of storage. An unquantized single Space is therefore impossible, which is why quantized demos of it run NVFP4 or float8 weights. Cut the Mini...

Market Signal

Why It Has Market Pull

The official demo Space from a funded, well-known Chinese frontier AI lab for its latest video model, which generates picture and synchronized stereo soundtrack (dialogue, music, foley) together in one pass, with a turbo LoRA cutting generation to as few as four sampling steps.

  • 429 Hugging Face likes, pinned on the lab's official org page
  • Published by the AI lab behind the model's text, multimodal, and video lines — a real, funded AI lab, not an individual upload
  • Eleven Hugging Face discussion threads, including an admin-merged safety guard for image-conditioned generations, showing active moderation and maintenance
  • The turbo LoRA claims roughly a 5x sampling speedup while improving face and finger micro-detail over the earlier checkpoint line
  • Independently covered by multiple industry blogs following the lab's video-model release

feedbacks

What People Are Saying

  • "Thanks for this Space — the unquantized setup is impressive and the README writeup is a great read."HF Space discussion

  • "Is there a demo that uses the other model that can take audio as input?"HF Space discussion

  • "[Admin] Add a safety prompt guard for image-conditioned generations"HF Space discussion (merged PR)

  • "One Song In, Four Shots Out, for under $5"Industry blog

  • "Its main strength is producing the picture and stereo soundtrack together, so speech, music, ambient sound, and visible events can stay aligned without a separate audio-generation pass."Trend coverage

  • "The lab releases its new video model on Hugging Face"Industry newsletter

HF Spaces104 likes

Blind A/B ranking of MiniMax-H3 acceleration variants Human-judged ranking of ~26 MiniMax-H3 acceleration variants over a 200-prompt corpus, from blind pairwise votes on pre-generated clips, with confidence intervals, cost and slice breakdowns. The design and its reasoning are in arena/DESIGN.md; the app's own notes are in arena/README.md. This Space is private and must stay private until deliberately flipped. It streams ~3,700 clips out of the private dataset multimodalart/h3-pre-gen-arena. See Going public below. hfoauth: true above creates the OAuth app and injects OAUTHCLIENTID, OAUTHCLIENTSECRET, OAUTHSCOPES and OPENIDPROVIDERURL. arena/space_auth.py implements the flow by hand (this is...

Market Signal

Why It Has Market Pull

This is a rigorous, blind-vote benchmarking arena rather than a generic model demo, built by a well-known Hugging Face creator to rank over twenty community speed variants of a frontier video model on quality, audio, and cost. It replaces self-reported speed claims with public, statistically scored community voting, and it launched to strong organic attention across Reddit and AI-focused newsletters.

  • Built by a Hugging Face staff-affiliated creator known for widely used community tools
  • Blind pairwise A/B voting across a 200-prompt, roughly 4,000-clip corpus covering 23+ rated acceleration variants, scored with Elo and Bradley-Terry ratings plus confidence intervals
  • Launch reportedly reached the top of two major image-generation subreddits the same day, drawing an estimated 226 upvotes and 49 comments
  • Independently covered by a ComfyUI-focused wiki and an AI-focused newsletter
  • 104 Hugging Face likes with active community-tab requests to add new models and replicate the methodology

feedbacks

What People Are Saying

  • "Great job!"HF Space community tab

  • "how to set this up for my own arena?"HF Space community tab

  • "requesting access to my own votes"HF Space community tab

  • "requested that another model variant be added to the comparison"HF Space community tab

  • "the announcement landed at the top of two major image-generation subreddits the same day"Reddit

  • "226 upvotes, 49 comments on the launch post"Reddit

  • "provides the first apples-to-apples comparison for this speedup ecosystem, replacing self-reported benchmarks"ComfyUI Wiki

HF Spaces53 likes

Put the person from a still into a driving video, in 4 steps Upload a driving video and a character still. The clip's first frame is repainted with gpt-image-2 so it shows your character in that exact pose and framing, and that repainted frame is the only conditioning the model gets besides the clip itself — no pose estimation, no segmentation, no masks. Takes 4–10 s of driving video and renders it at 4 sampling steps; anything longer is cut to 10.1 s. The model itself only renders frame counts of the form 17k+5 and never fewer than 124 (5.17 s), so shorter clips are held out to 124 frames with a frozen last frame and the render is trimmed back — what comes out is exactly as long as what wen...

Market Signal

Why It Has Market Pull

The official demo Space from a funded AI-video startup known for a viral character-swap trend, showcasing its newest model-backed pipeline that repaints a person into a driving video from a single edited frame, already picked up by independent tool authors and video creators.

  • Published under the verified official org account, not a fan clone — separate community reuploads of the same demo also exist, confirming demand
  • Live for under two weeks at evaluation time
  • A large finetune of a frontier video model's transformer, claimed to render significantly faster than a leading open competitor on matched hardware
  • Independent tool integration shipped within days plus a dedicated tutorial video
  • Endorsed publicly on X by a widely followed AI-tooling influencer

feedbacks

What People Are Saying

  • "You guys really gotta try this model, it's amazing. Just 3 steps to generate the videos."X reply

  • "Replaces the character in a video with whatever you paint into one of its own frames — motion, camera and timing untouched."AI-tooling news writeup

  • "ComfyUI nodes for the new model finetune"GitHub (independent integration)

  • "Character Replacement Tutorial"YouTube video title

  • "While not perfect yet, this marks a significant leap forward, showcasing the growing potential of this technology with every update."Newsletter writeup

  • "Independent third-party coverage is still thin."evidence gap

Sources

GitHub

🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.

A spy satellite simulator in your browser, except the data is real. Live open source spatial intelligence on a photorealistic 3D globe.

Run frontier MoE models on hardware you already own — pure C, zero deps, experts streamed from disk. Tiny engine, immense model. 🐦

VoiceStudio is the open-source, fully-local ElevenLabs alternative — voice cloning, voice design, video dubbing, dictation, transcription & audiobook creation in 646 languages.

Fully autonomous AI Agents system capable of performing complex penetration testing tasks

Fast, efficient, battle-tested at Alibaba's scale. Hybrid architecture code review tool: deterministic pipelines + LLM Agent, precise line-level comments, built-in multi-language ruleset (NPE, thread-safety, XSS, SQL injection), OpenAI & Anthropic compatible.

Product Hunt

Youkti keeps a memory of every account, conversation, and deal, then tells your sales team the exact next move: which deal is slipping, which dormant account just fired a signal, what to prep for tomorrow's meeting. Built for AEs, RevOps, and outbound reps. Contact data, buying signals, and intent are all free, no card, no meter.

Cortex is an open source API knowledge layer that turns OpenAPI, AsyncAPI, GraphQL, gRPC, and OpenRPC specs into interactive documentation, typed SDKs in 11 languages, and MCP servers for AI agents.

QApilot MCP automates tests on real Android devices and emulators by talking to Claude, Cursor or Codex. Describe a test flow in plain English, no Appium code required. Your agent lays out the steps. QApilot runs the steps. It finds the elements, waits for the screen to settle, retries when something moves, and caches what it learns so repeat runs are faster. Every pass saves a Gherkin feature file and becomes a replayable test case. Needs Node, Java and the Android SDK.

ABrush brings leading AI models and production-ready advanced AI workflows into the environment where artists already work. We use AI to remove repetitive production work, accelerate iteration, and give artists more time for creative decisions, while keeping the artist in control of the final result. AI speeds up the process and cuts the cost of routine. Created by artists, for artists.

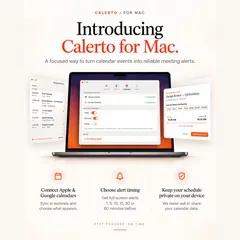
Calerto turns your calendar into alarms you can't sleep through. Full-screen meeting alerts — not another notification you'll swipe away — with custom prep time per meeting, Apple + Google Calendar sync, a menu bar countdown to what's next, and automatic launch at login (toggle it off anytime). Pause alarms without losing them. Pro auto-alarms your whole week. Your calendar data never leaves your device. Never be late again.

Turn Noida, Delhi, Gurugram or Bengaluru into a battle with friends. Drag to send supporters, capture territory and hold 75% of the map to win. Play solo against bots or in a room of up to 8. Free in your browser. No download or account needed.

Hacker News

Hey HN, we’re Nischal & Naman. We’re brothers, and together we’re building an open-source platform for simulation based testing of voice agents (try it out in 5 mins - https://docs.egma.ai/docs/get-started/quickstart , 2 min demo video - https://youtu.be/wgDWEe5UAUY ) Platforms that help you do simulation testing already exist. But they all charge a heavy premium on top of inference costs. We believe if the industry truly wants to scale simulation testing of voice agents, we need to stop chargin... (16 points, 6 comments).

This MCP plugin implements a "Programmatic Tool Calling" mode, inspired by the idea described in this Anthropic article ( https://www.anthropic.com/engineering/advanced-tool-use ). (4 points, 0 comments).

My company stopped allowing Navicat because of compliance policy. DBeaver worked, but I don't like it. I kept running into two recurring issues. First, production investigations often require several queries across different databases. I would query one table, copy an ID into another query, wait for the result, and repeat the process several times. I started wondering if there was a way to handle this without writing a separate script for every case. What if I had a simple form where I could ent... (4 points, 1 comments).

I wanted to share my side-project: gPTY. Started off as an idea to combine Godot and Rust in a project (two stacks I wanted to use more to learn more). The base inspiration was tmux - simply allow spawning multiple PTYs and then let the user grid/tile them how they see fit. But since we have the Godot game engine at our disposal, we can do some more interesting things, like add an FPS counter, and then subsequently also let people set their preferred FPS (the idea being the potential lower power... (94 points, 48 comments).

Firefox Extension/Userscript and API to get Pangram scores for all articles on the hackernews frontpage. The extension allows you to hide articles with a high score. This is about detecting posts written by LLMs, not posts about AI. Feel free to use the API to build your own tooling/readers. Big thanks to https://news.ycombinator.com/user?id=salahadawi for providing the data :). (16 points, 3 comments).

Type. The model is already answering. There is no send button. Left pane is one long draft. Right pane is a stack of replies. Pause for ~350ms and it fires a normal streaming chat completion with the whole draft. Type again and it aborts the last request if that reply never produced text; if it did, that bubble stays and a new one stacks. Bubbles never rewrite. Enter is a newline. That is overlapping unary streams, not a duplex socket. Same shape as ghost-text, pointed at a conversation instead... (7 points, 3 comments).

HF Spaces

Simulate a fruit fly in your browser using WebGPU kernels A standalone fruit fly connectome demo: paint neurons, stimulate the network, and watch an articulated Three.js fly respond. Vanilla JavaScript, Vite, Three.js, and @huggingface/kernels. Simulated neural activity drives crafted walking, turning, and flight animations. The movements are illustrative, not validated predictions of fly behavior. Open the address printed by Vite, then click Download & start. All neural weights, fly meshes, fonts, and kernel templates are included in public/; setup loads them into the browser and caches verified weight chunks. No API key or external model service is required. Deploy the generated dist/ dire...

generate a video from an image with a text prompt Wan2.2 14B Fast Preview is a Hugging Face Space tagged with gradio, mcp-server, region:us. It has 2075 likes on Hugging Face.

Use multiple FLUX.2-Klein LoRAs Note: This space is experimental and may log image-uploads during certain periods for performance monitoring. Always comply with HF and model Terms of Service. Any stored images are automatically deleted after 7 days. FLUX.2 Klein multi-LoRA is a Hugging Face Space tagged with gradio, mcp-server, region:us. It has 559 likes on Hugging Face.

Demo of the Collection of Qwen Image Edit LoRAs Prompt-based image editing on Qwen-Image-Edit-2511, with identity preservation (change pose/clothes/scene while keeping the person's face), HD output, and an anti-deformed-hands option. The Space exposes one endpoint: /edit. Base URL / Space id: kulkas2pintu/QWENEDITIMAGE. | name | type | default | meaning | |---|---|---|---| | image | image (filepath/URL) | — | required. The image to edit (the person/subject whose identity is kept). | | prompt | str | — | required. What to change, e.g. "change her outfit to a red dress; turn to look left". | | loraadapter | str | "" | Optional style LoRA name (see list below). "" = no style / base edit. | | im...

Video generation with a synchronized soundtrack MiniMax-H3 — unquantized, split across two Spaces Joint video and soundtrack out of a single denoising pass, at bfloat16 with no quantization anywhere. This Space is the denoising half: the 61.73 GiB transformer and the two autoencoders. The 62.14 GiB Qwen3-VL conditioner runs in qwen3vl-conditioner, which this Space calls over the gradio API for every request. The weights are the public MiniMaxAI/MiniMax-H3 diffusers checkpoint. MiniMax-H3 is 195.9 GiB in bfloat16 and a ZeroGPU Space is evicted at 150 GB of storage. An unquantized single Space is therefore impossible, which is why quantized demos of it run NVFP4 or float8 weights. Cut the Mini...

Demo of the Collection of Qwen Image Edit LoRAs QIE-2511 Rapid-AIO LoRAs Fast (Experimental) is a Hugging Face Space tagged with gradio, mcp-server, region:us. It has 164 likes on Hugging Face.