The Research Desk.

The most upvoted and starred AI research crossing the community today.

Last Brew Time: Oct 25, 2026, 11:30 AM PT

X.com Research Buzz

NLP
The Algorithmic Self-Portrait: Deconstructing Memory in ChatGPT
X.com
7285

The Algorithmic Self-Portrait: Deconstructing Memory in ChatGPT

Financing the AI Buildout
X.com
6443

Financing the AI Buildout

Stijn Van Nieuwerburgh

Columbia Business School
AlphaXiv Trending

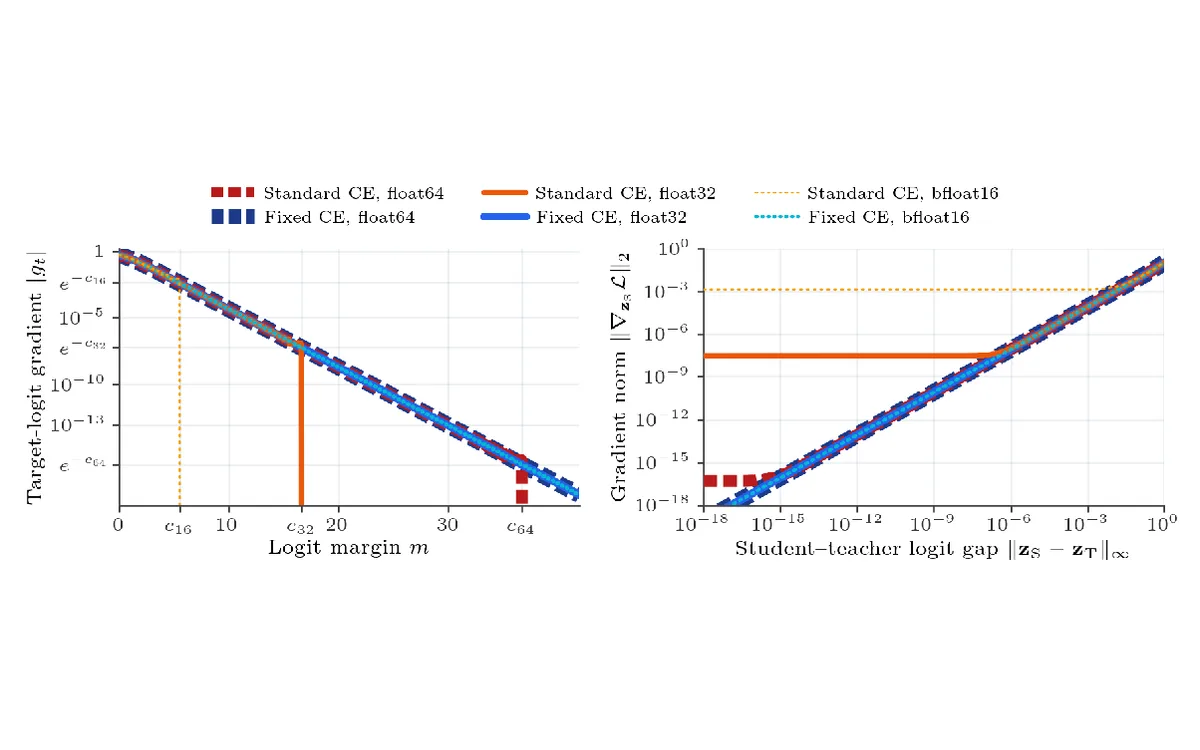
A Fix for Softmax and Cross-Entropy
AlphaXiv
203

A Fix for Softmax and Cross-Entropy

6k, Views

Affiliation: Google DeepMind, Google DeepMind
Reinforcement Learning
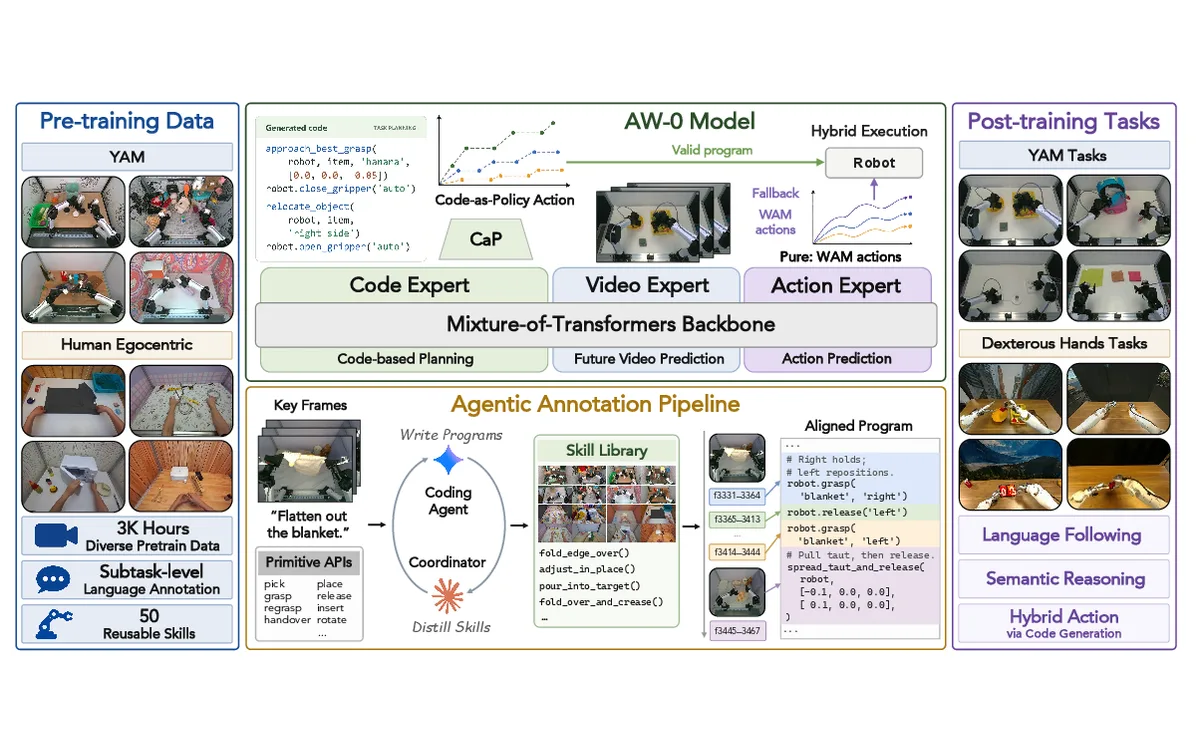
Agentic World Action Models
AlphaXiv
139

Agentic World Action Models

2k, Views

NVIDIA, University of Pennsylvania

AlphaXiv
103

Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence

3k, Views

Action Learning for Scientific Simulations
AlphaXiv
28

Action Learning for Scientific Simulations

Views

Affiliation: Kempner Institute Harvard University Microsoft Research New England Website Code, Kempner Institute, Harvard University, Microsoft Research New England
Native Real-Time Interactive Omni Intelligence: A Unified Framework
AlphaXiv
6

Native Real-Time Interactive Omni Intelligence: A Unified Framework

Real-Time Closed-Loop Driving With Frozen DINOv2-Laya Spatial Pooling and Quintic Path Tracking
AlphaXiv
5

Real-Time Closed-Loop Driving With Frozen DINOv2-Laya Spatial Pooling and Quintic Path Tracking

HuggingFace Daily Papers

NLP
Different Tasks, Different Timesteps: Temporal Task-Aware Quantization for Diffusion Language Models
HuggingFace
23

Different Tasks, Different Timesteps: Temporal Task-Aware Quantization for Diffusion Language Models

Ofek Avivi, Eliron Rahimi, Avi Mendelson, Chaim Baskin

Reinforcement Learning
EvalResearchBench: Can AI Agents Build Their Own Feedback for Recursive Self-Improvement?
HuggingFace
21

EvalResearchBench: Can AI Agents Build Their Own Feedback for Recursive Self-Improvement?

Yaolun Zhang, Tianyi Xu, Yujie Zhao, Jishen Zhao, Qingyun Wu

AG2AI

NLP
The LLM-Attacker: A Unified Red-Team Framework for Privacy Evaluation of Split and Distributed LLM Systems
HuggingFace
9

The LLM-Attacker: A Unified Red-Team Framework for Privacy Evaluation of Split and Distributed LLM Systems

Georgios Politis, Evangelos Pappas

Setloop

NLP
Diffusion Language Models Change Speed Across Tasks and Languages
HuggingFace
9

Diffusion Language Models Change Speed Across Tasks and Languages

Mohsen Fayyaz, Ali Modarressi, Daniel Israel, Lucas Bandarkar, Nanyun Peng

UCLA NLP

Reinforcement Learning
TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments
HuggingFace
8

TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments

Yicheng Xu, Zhikai Xu, Ziyuan Chen, Yuhang Dong, Tao Zhang

Reinforcement Learning
Bridging Exploration and Persona: Information-Directed Dueling for Test-Time Agent Personalization
HuggingFace
7

Bridging Exploration and Persona: Information-Directed Dueling for Test-Time Agent Personalization

Jie Mao, Pingchen Lu, Xiangyi Wang, Hengquan Huang, Shuang Qiu