The Research Desk.

The most upvoted and starred AI research crossing the community today.

Last Brew Time: Oct 24, 2026, 12:06 PM PT

X.com Research Buzz

NLP
Why are all LLMs Obsessed with Japanese Culture? On the Hidden Cultural and Regional Biases of LLMs
X.com
12667

Why are all LLMs Obsessed with Japanese Culture? On the Hidden Cultural and Regional Biases of LLMs

NLP
The Algorithmic Self-Portrait: Deconstructing Memory in ChatGPT
X.com
7283

The Algorithmic Self-Portrait: Deconstructing Memory in ChatGPT

Max Planck Institute for Informatics, Ruhr University Bochum, IIT Kharagpur, TU Delft

Financing the AI Buildout
X.com
6444

Financing the AI Buildout

Stijn Van Nieuwerburgh

Columbia Business School
AlphaXiv Trending

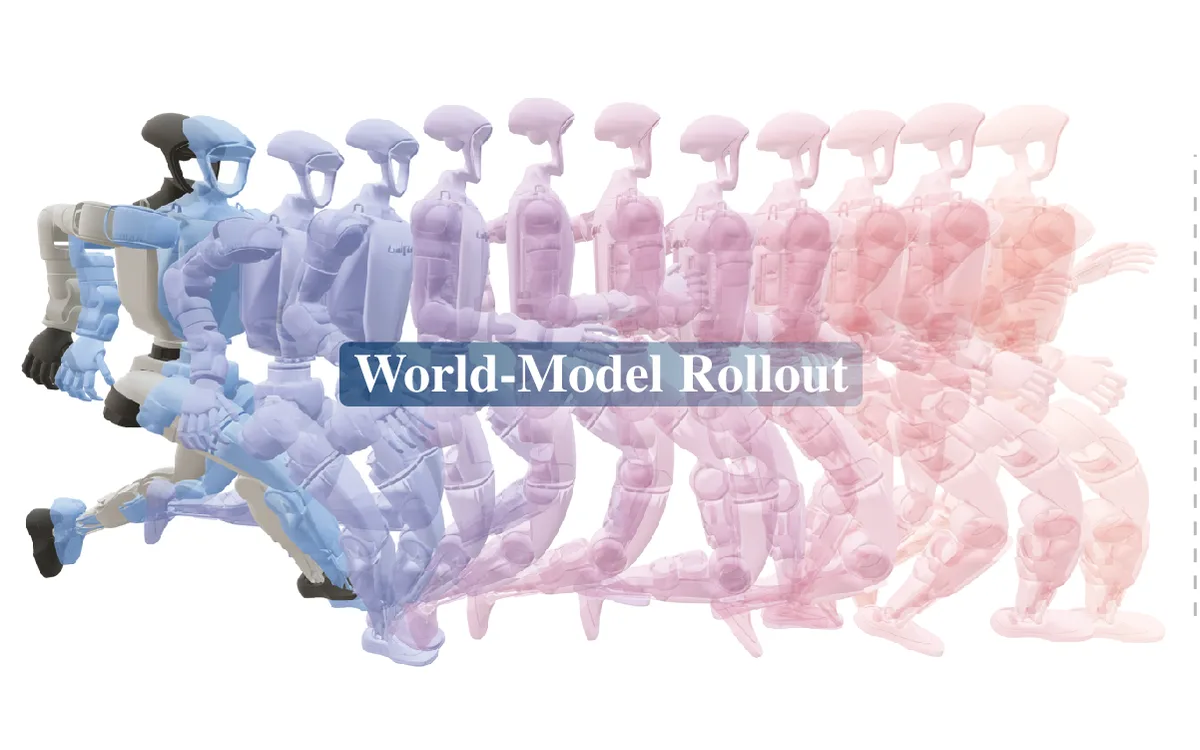
SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model
AlphaXiv
228

SuperMimic: Scaling Humanoid Whole-Body Control with One Differentiable World Model

4k, Views

Reinforcement Learning
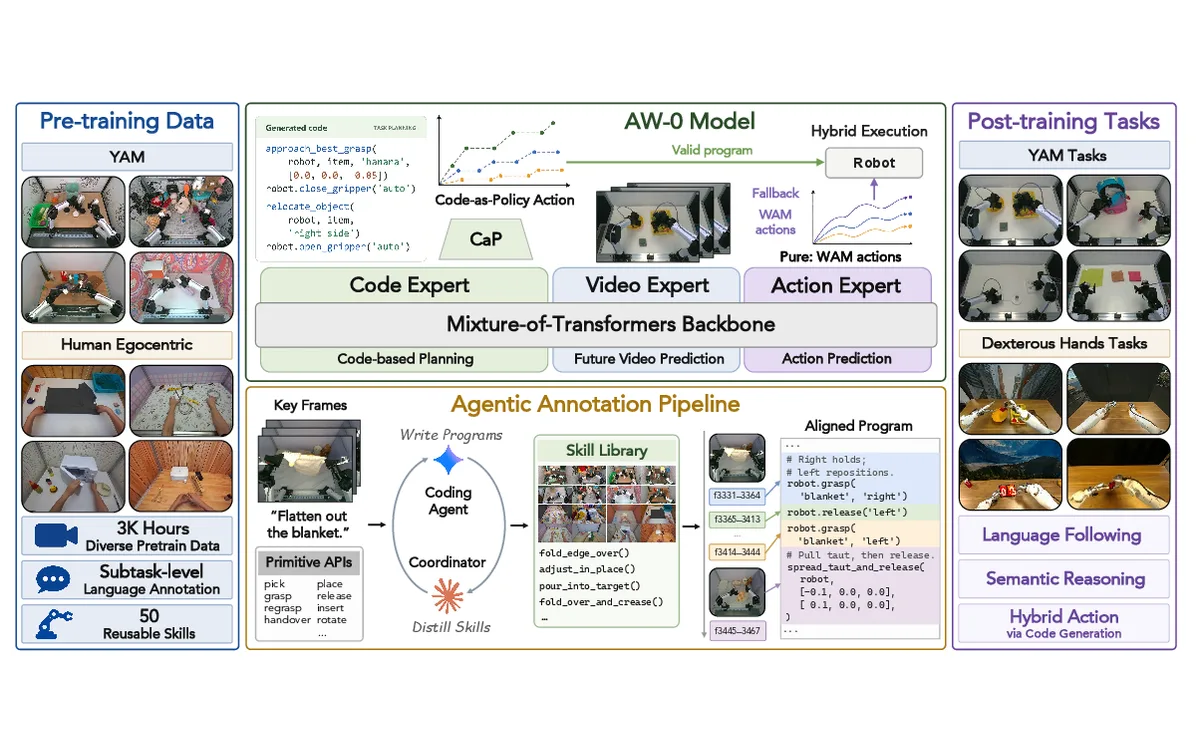
Agentic World Action Models
AlphaXiv
116

Agentic World Action Models

1k, Views

NVIDIA, University of Pennsylvania
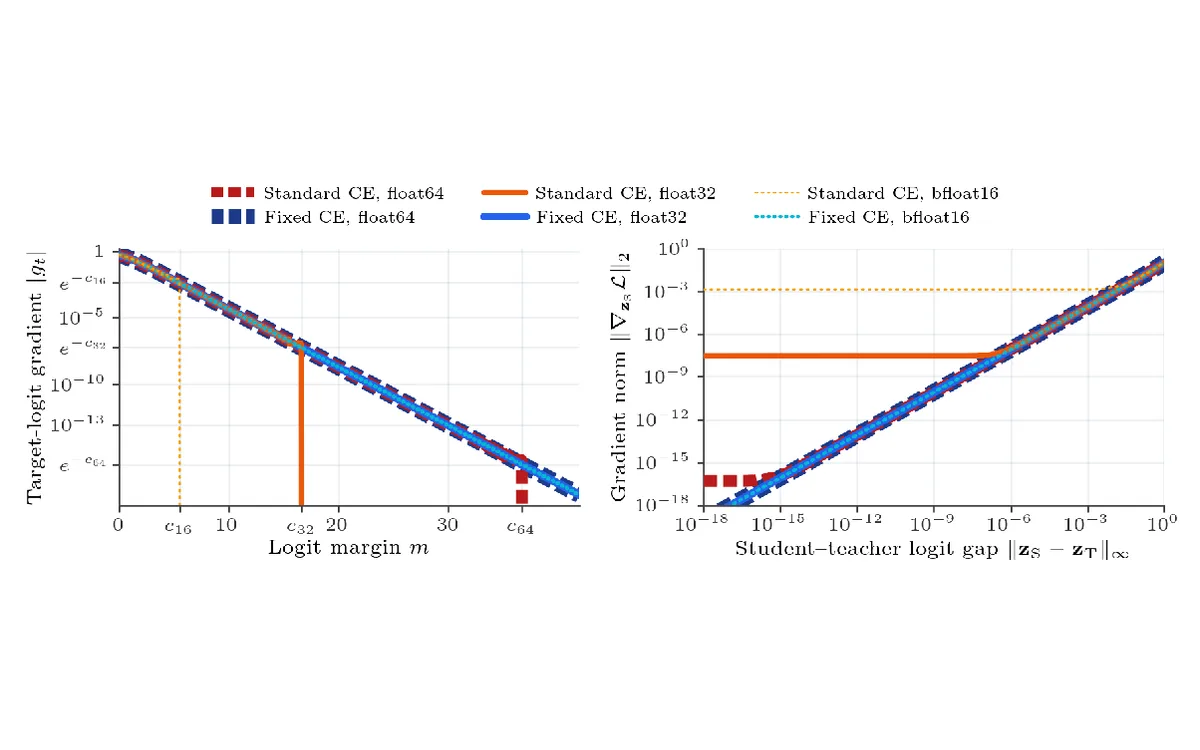
A Fix for Softmax and Cross-Entropy
AlphaXiv
85

A Fix for Softmax and Cross-Entropy

2k, Views

Affiliation: Google DeepMind, Google DeepMind

AlphaXiv
73

Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence

2k, Views

Computer Vision
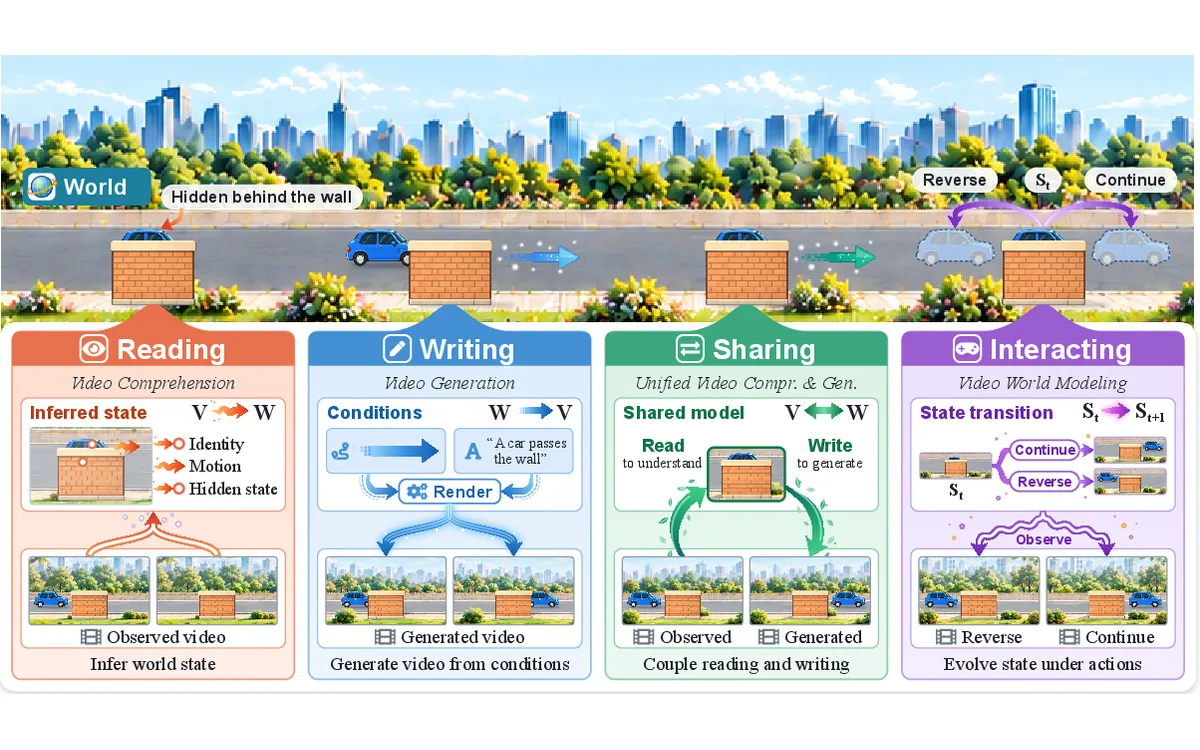
Reading, Writing, Sharing, and Interacting with the World through Video
AlphaXiv
18

Reading, Writing, Sharing, and Interacting with the World through Video

Views

Affiliation: University of Oxford, Affiliation: University of California, Merced, University of Oxford, University of California, Merced
Action Learning for Scientific Simulations
AlphaXiv
12

Action Learning for Scientific Simulations

Affiliation: Kempner Institute Harvard University Microsoft Research New England Website Code, Kempner Institute, Harvard University, Microsoft Research New England

HuggingFace Daily Papers

NLP
Different Tasks, Different Timesteps: Temporal Task-Aware Quantization for Diffusion Language Models
HuggingFace
15

Different Tasks, Different Timesteps: Temporal Task-Aware Quantization for Diffusion Language Models

Ofek Avivi, Eliron Rahimi, Avi Mendelson, Chaim Baskin

NLP
The LLM-Attacker: A Unified Red-Team Framework for Privacy Evaluation of Split and Distributed LLM Systems
HuggingFace
4

The LLM-Attacker: A Unified Red-Team Framework for Privacy Evaluation of Split and Distributed LLM Systems

Georgios Politis, Evangelos Pappas

Setloop

NLP
Diffusion Language Models Change Speed Across Tasks and Languages
HuggingFace
3

Diffusion Language Models Change Speed Across Tasks and Languages

Mohsen Fayyaz, Ali Modarressi, Daniel Israel, Lucas Bandarkar, Nanyun Peng

UCLA NLP

Reinforcement Learning
TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments
HuggingFace
2

TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments

Yicheng Xu, Zhikai Xu, Ziyuan Chen, Yuhang Dong, Tao Zhang

Reinforcement Learning
EvalResearchBench: Can AI Agents Build Their Own Feedback for Recursive Self-Improvement?
HuggingFace
2

EvalResearchBench: Can AI Agents Build Their Own Feedback for Recursive Self-Improvement?

Yaolun Zhang, Tianyi Xu, Yujie Zhao, Jishen Zhao, Qingyun Wu

AG2AI

Reinforcement Learning
Bridging Exploration and Persona: Information-Directed Dueling for Test-Time Agent Personalization
HuggingFace
1

Bridging Exploration and Persona: Information-Directed Dueling for Test-Time Agent Personalization

Jie Mao, Pingchen Lu, Xiangyi Wang, Hengquan Huang, Shuang Qiu