The Research Desk.

The most upvoted and starred AI research crossing the community today.

Last Brew Time: Sep 25, 2026, 11:31 AM PT

X.com Research Buzz

The Machine-Native Economy: How digital assets connect intelligence, commerce, and compute
X.com
10830

The Machine-Native Economy: How digital assets connect intelligence, commerce, and compute

BlackRock

NLP
Large-scale online deanonymization with LLMs
X.com
4601

Large-scale online deanonymization with LLMs

Daniel Paleka, Joshua Swanson, Michael Aerni, Florian Tramèr, Simon Lermen

ETH Zurich, Anthropic

Jev in the Wild: A Data-Driven Analysis of the Jev Model's Functionality, Applications and Ecosystem
X.com
3791

Jev in the Wild: A Data-Driven Analysis of the Jev Model's Functionality, Applications and Ecosystem

TypeSafe AI

AlphaXiv Trending

Reinforcement Learning
RRSI: Regularized Recursive Self-Improvement of Agent Harnesses
AlphaXiv
164

RRSI: Regularized Recursive Self-Improvement of Agent Harnesses

Affiliation: Stanford University, Affiliation: Washington University in St. Louis, This work was done while Peng was a Student Researcher at Google Cloud AI Research, Cloud AI Research, Stanford University
Memory Attention
AlphaXiv
96

Memory Attention

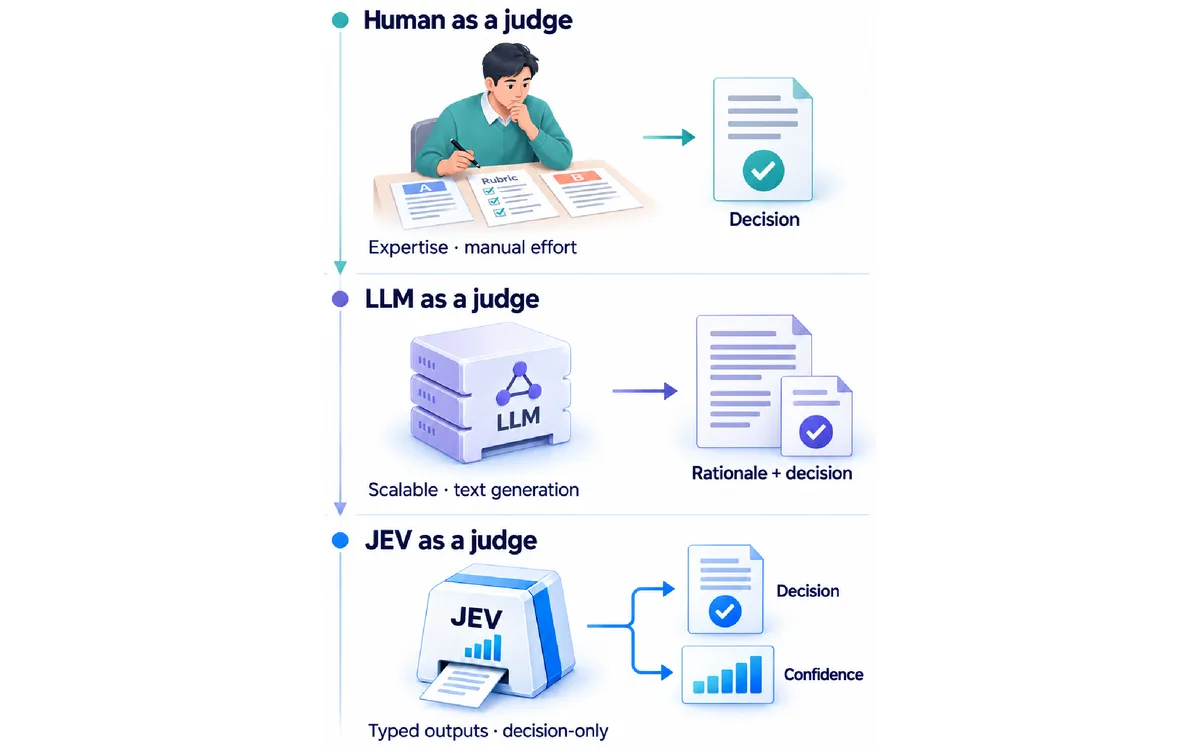
JEV-as-a-Judge: Accept When Confident, Escalate When Unsure
AlphaXiv
69

JEV-as-a-Judge: Accept When Confident, Escalate When Unsure

Affiliation: Carnegie Mellon University, Carnegie Mellon University
Efficiency
InternW0: A Foundational Physical World Model for Efficient Real-World Interactions
AlphaXiv
29

InternW0: A Foundational Physical World Model for Efficient Real-World Interactions

Shanghai AI Laboratory

Machine Learning
Self-Play Pretraining with Zero Data
AlphaXiv
13

Self-Play Pretraining with Zero Data

Affiliation: Tel Aviv University, Affiliation: Stanford University, Tel Aviv University, Stanford University
Reinforcement Learning
Agents Can Learn Covert Communication at Test Time Without Explicit Negotiation
AlphaXiv
13

Agents Can Learn Covert Communication at Test Time Without Explicit Negotiation

HuggingFace Daily Papers

NLP
Your Transformer Can Hold Two Thoughts at Once: Evidence of Linear Superposition in LLMs
HuggingFace
50

Your Transformer Can Hold Two Thoughts at Once: Evidence of Linear Superposition in LLMs

Pavel Tikhonov, Anton Korznikov, Matvey Mikhalchuk, Nikita Dragunov, Temurbek Rahmatullaev

Speech Audio
Parts-of-Speech as Emergent Categories in SAE Latent Space
HuggingFace
10

Parts-of-Speech as Emergent Categories in SAE Latent Space

Alessandro Bondielli, Lucia Passaro, Serena Auriemma, Alessandro Lenci

CoLingLab | Computational Linguistics Laboratory - University of Pisa

Reinforcement Learning
Coding Agents for Generalized Task and Motion Planning Problems
HuggingFace
6

Coding Agents for Generalized Task and Motion Planning Problems

Matteo Merler, Bowen Li, Josh Roy, Yichao Liang, Qianwei Wang

Fondazione Bruno Kessler - NLP Unit

Computer Vision
RGBD20K: A Large-Scale Benchmark for RGB-D Semantic Segmentation
HuggingFace
5

RGBD20K: A Large-Scale Benchmark for RGB-D Semantic Segmentation

Shaohua Dong, Zexuan Meng, Haiyan Sun, Bing Fan, Cuicui Zhang

University of North Texas

Computer Vision
AV-GRPO: Modality-Anchored Decoupling Diffusion Reinforcement Learning for Joint Audio-Video Generation
HuggingFace
2

AV-GRPO: Modality-Anchored Decoupling Diffusion Reinforcement Learning for Joint Audio-Video Generation

Zhiyu Xu, Weilong Yan, Yufei Shi, Shiyang Li, Yihao Liu

Shanghai AI Laboratory

Reinforcement Learning
Just Ask Jev: Reinforcement Learning for Calibrated Decisions as a Zero-Shot Detector of AI Alignment Failures
HuggingFace
2

Just Ask Jev: Reinforcement Learning for Calibrated Decisions as a Zero-Shot Detector of AI Alignment Failures

Ruoqi Guo, Yi Liu, Gelei Deng, Yuekang Li, Lida Zhao