A Rival's Model Is Doing Google's Optimization Work
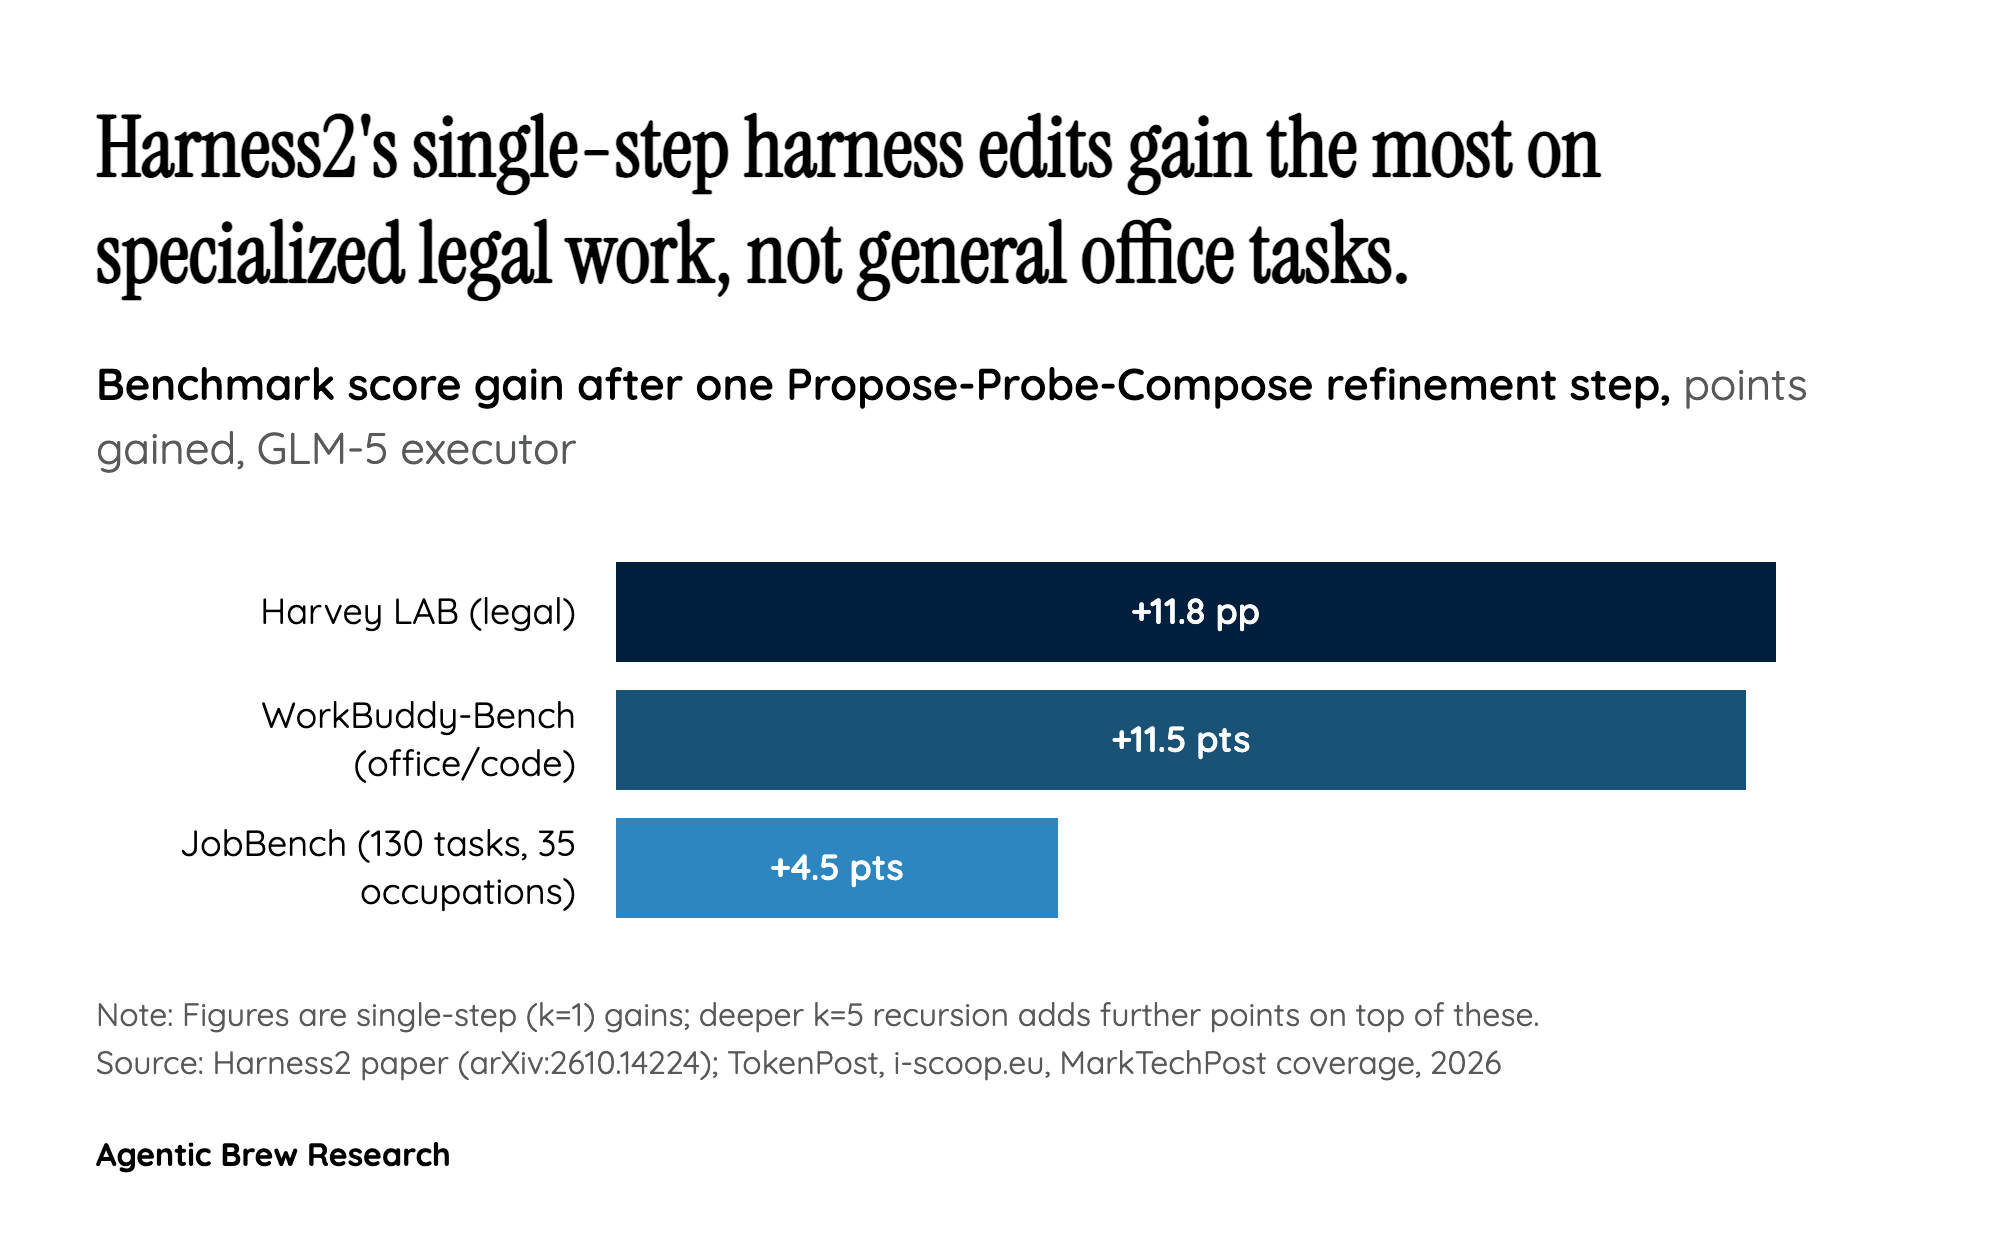
The most striking detail buried in Google's own writeup is who actually does the thinking inside Harness2. The executor agents being improved ran on Gemini 3.5 Flash and GLM-5, but the editor model that proposes and composes every harness edit in Google's benchmarks was Claude Opus 4.8, built by Anthropic, a direct competitor [6]. In other words, Google's flagship self-improvement framework, when put through its own published experiments, leaned on a rival lab's model to generate the actual improvements. That is a quiet admission that the editing step - the part that decides what a system prompt, guardrail, or skill should say next - is a distinct and apparently hard capability, one Google didn't default to its own models for when it mattered.