From Pipeline to Unified Video-to-Video: How Griffin Achieves Full-Duplex Realism
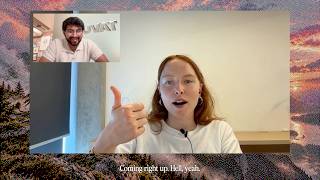
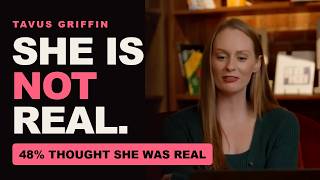
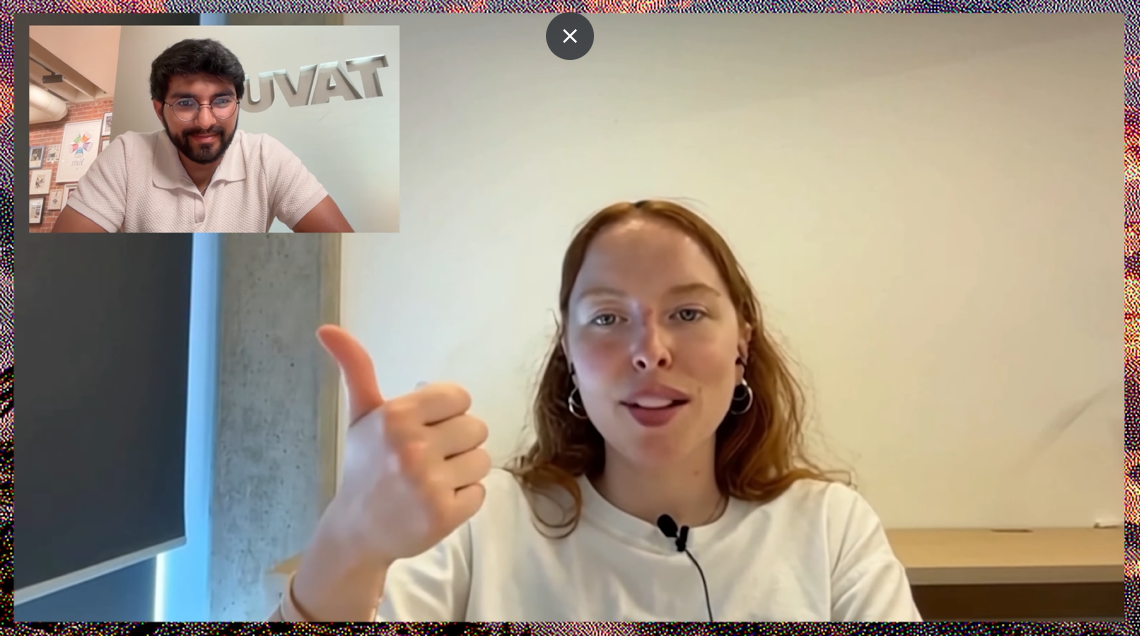
Tavus built Griffin to replace the old assembly line of separate speech-recognition, language-model, speech-synthesis, and avatar-rendering components with a single unified video-to-video system [1]. That collapse is what makes full-duplex behavior possible - instead of waiting for a speaker to finish before generating a reply, Griffin continuously reassesses the conversation several times a second, letting it backchannel, tolerate interruptions, and track silence duration like a real phone call [2]. Tavus's own launch materials lean into that self-awareness rather than hide it: its official demo video stages the reveal as a video call where one participant turns out to be the AI, with dialogue that jokes about 'passing a Turing test soon' and a 'stop trying to explain it, just show them' pitch for the whole launch, while a more conventional BusinessWire press-release video covered the same announcement in formal terms. The naturalness shows up in smaller, unscripted moments too - one early tester described hopping on a call with Griffin while running a fever, and having the model respond 'oh no kai, a fever is the worst' and ask whether he'd taken anything, the kind of contextually grounded reaction a chained pipeline of separate components struggles to improvise. The payoff also shows up in the harder numbers - Griffin-Lite streams 720p video in 320-millisecond chunks via a streaming autoregressive diffusion model, averaging 0.43 seconds of audio-to-video latency on NVIDIA H100 chips [1][4]. By that measure it looks slower than Tavus's own prior model, Phoenix-4.5, which cited 134ms latency and was marketed as the fastest in market [7]- though the two numbers may not be measuring quite the same thing, since Griffin's figure describes end-to-end audio-to-video response time while Phoenix-4.5's describes per-frame rendering latency. Even allowing for that caveat, Phoenix-4.5 fooled only 2.4% of participants in a comparable study, so raw speed alone clearly isn't what explains believability; conversational timing and multimodal coherence appear to matter more.