The Real Story Is Cost-Per-Task, Not Raw Benchmarks
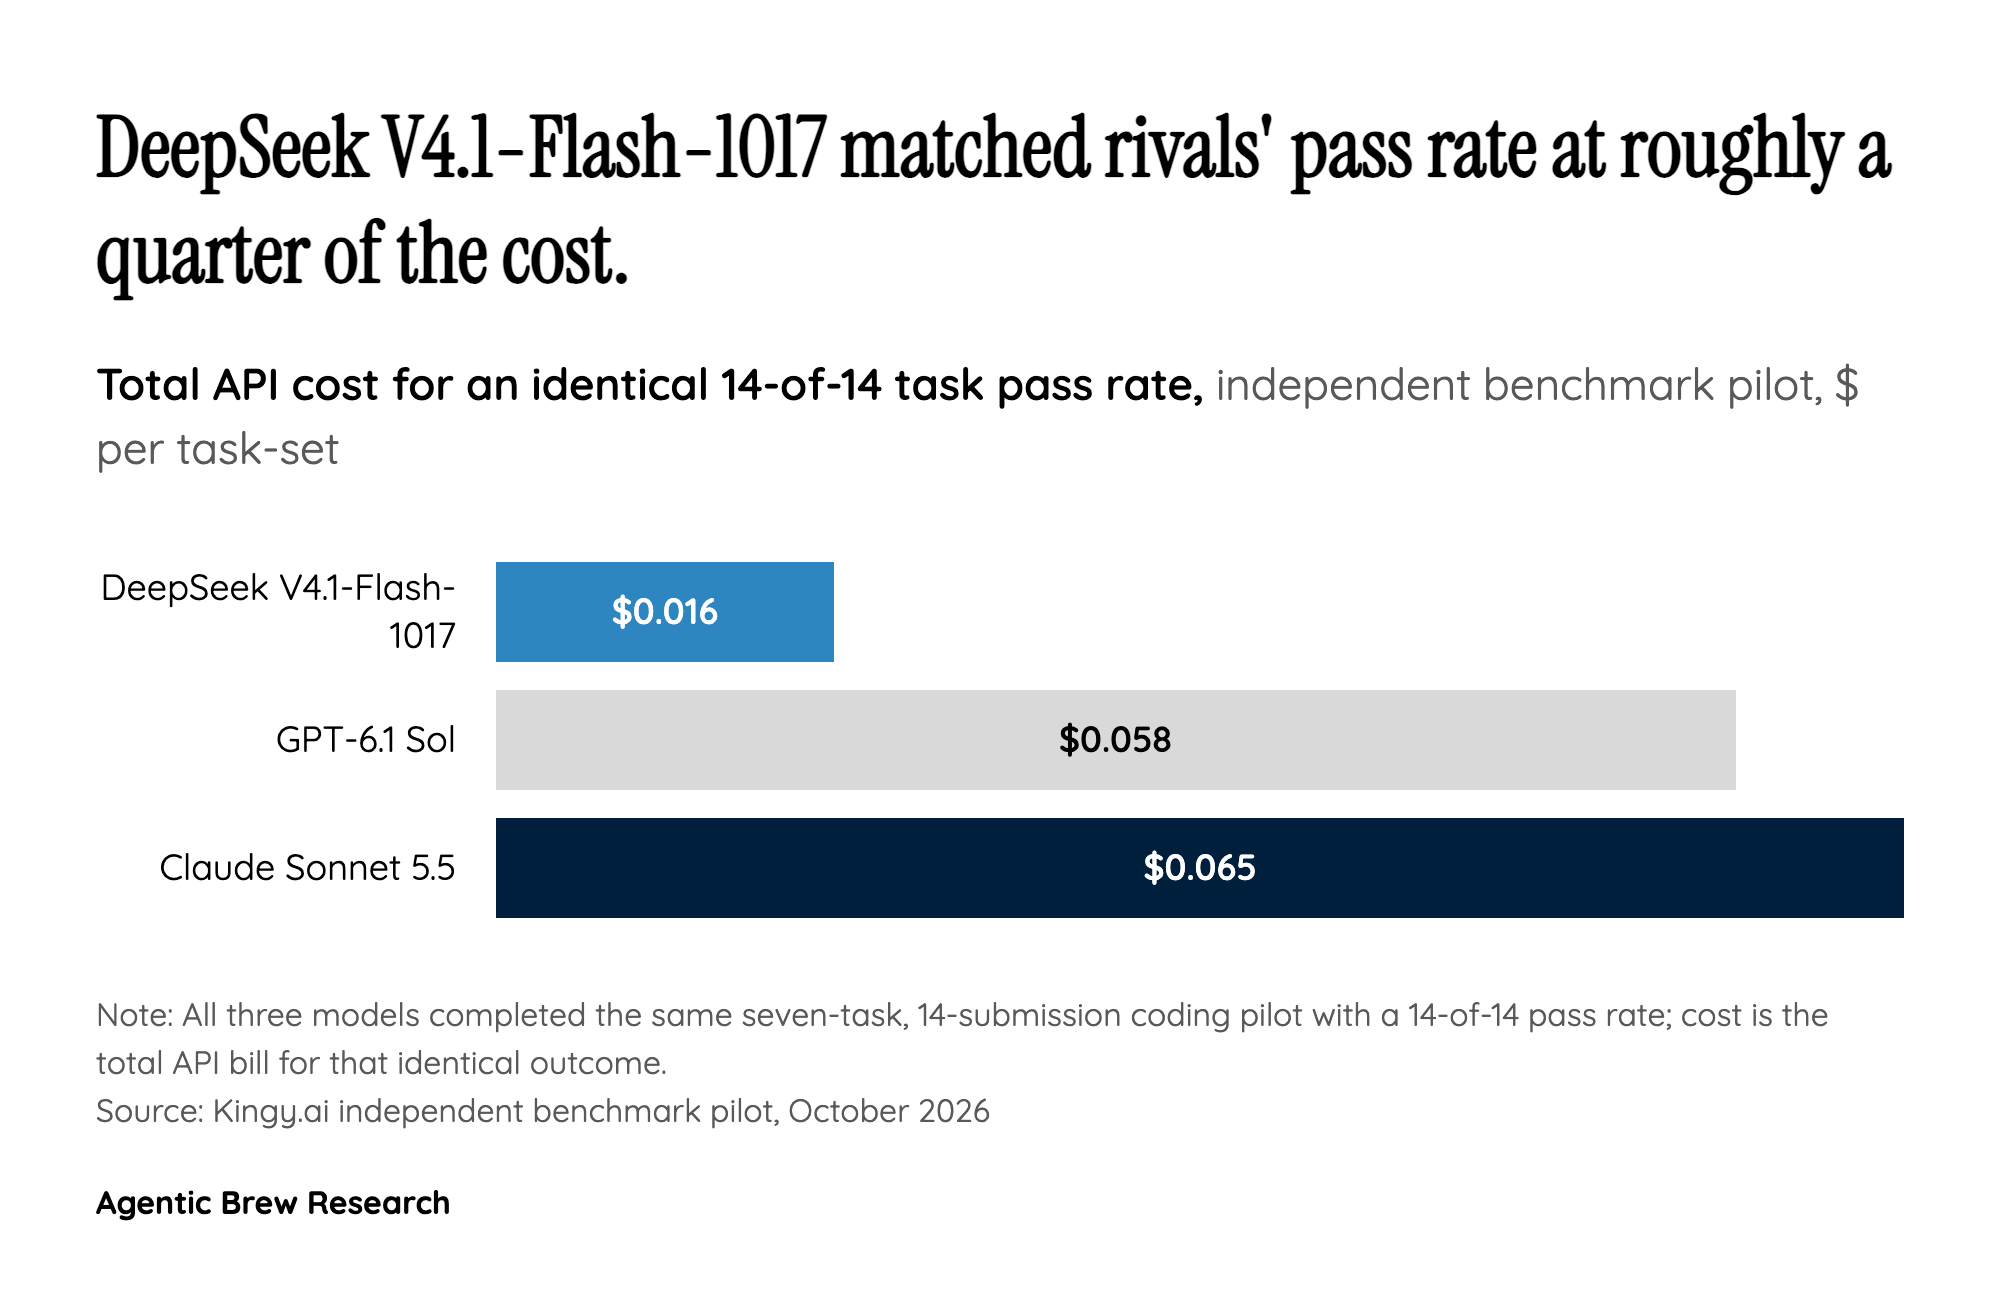
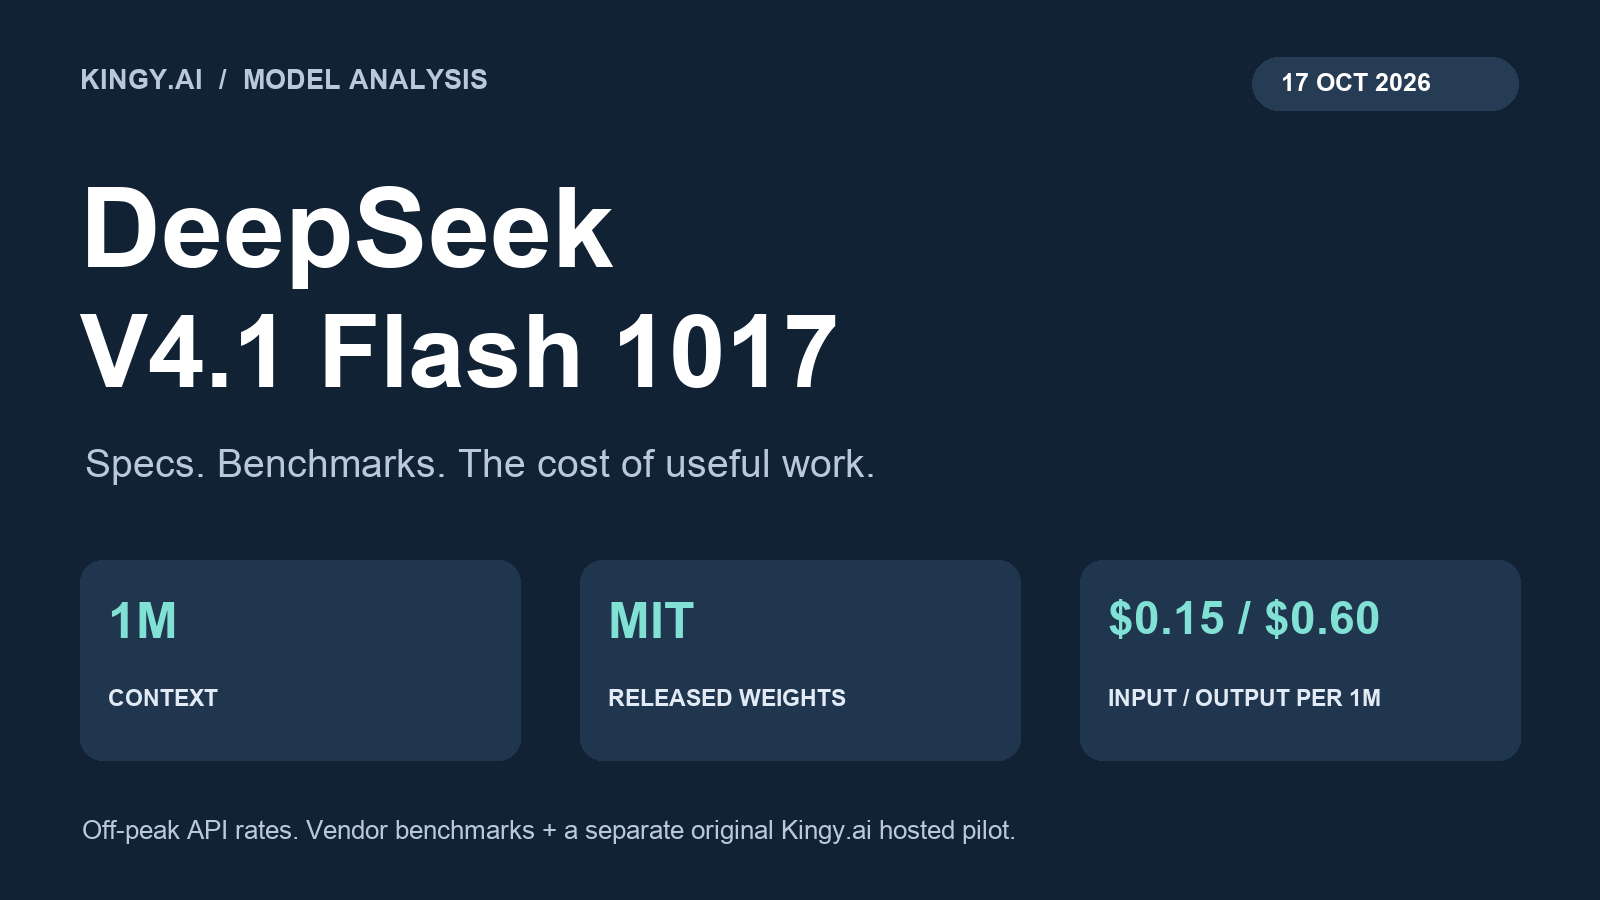
DeepSeek's own release notes brand V4.1-Flash-1017 a 'Pareto improvement' - better benchmarks, faster completion, and shorter outputs at the same price [1]- but the more consequential number comes from an independent reviewer. Kingy.ai ran a hosted pilot of coding tasks and found Flash 1017 matched the 14-of-14 pass rate of GPT-6.1 Sol and Claude Sonnet 5.5 while the total API cost came to $0.0157, versus $0.0577 for GPT-6.1 Sol and $0.0653 for Claude Sonnet 5.5 for the identical result [2]. That is the kind of gap that pressures pricing across the industry, not a marginal efficiency tweak.
The caveat worth keeping is that DeepSeek is not simply 'better' across the board. The same independent review found Claude Opus 5 still wins outright on 7 of the 11 published benchmarks it compared, even as DeepSeek leads specifically on DeepSWE, Automation-Bench, Agents' Last Exam, and Apex Bench [2]. DeepSeek's own benchmark table shows where those agentic-task gains actually come from versus its immediate predecessor: Terminal-Bench 4.0 climbed from 31.2 to 42.3, DeepSWE v1.1 from 74.2 to 77.0, and Automation-Bench v1.0.6 from 54.8 to 60.5 [3]. Vercel's AI Gateway changelog echoes the same framing from a deployment angle, noting the model finishes agent runs faster and with fewer output tokens than the prior snapshot [4].