Rise of local, on-device AI for privacy
TECH

Rise of local, on-device AI for privacy

31+
Signals

Strategic Overview

  • 01.
    A growing wave of consumers is moving from cloud-based AI to local AI that runs directly on personal hardware, driven by privacy concerns over data collection by cloud providers.
  • 02.
    Apple plans to make on-device AI a central focus of WWDC 2026, leveraging its custom silicon to position local processing as a competitive advantage over cloud-dependent rivals.
  • 03.
    Google announced 'AI seal,' a new Android feature that hardware-isolates on-device AI workloads from the rest of the operating system using virtual machines, in response to prior Gemini assistant vulnerabilities.
  • 04.
    A writer running an open-source Hermes Agent with a 125-billion-parameter Qwen model on an M5 Ultra Mac Studio found local setups can now rival cloud assistants for everyday personal-assistant tasks, run continuously, with zero added API cost.
  • 05.
    A reviewer who self-hosted local LLMs found the core obstacle isn't model quality but setup friction: driver conflicts, PATH issues, missing DLLs, and a learning curve requiring research into quantization, context length, and inference backends before getting any value.
  • 06.
    macOS can put a Mac to sleep mid-task, killing any long-running local AI session; the common workaround is the built-in 'caffeinate' command or adjusting Energy Saver settings, though Apple Silicon's lid-close sleep cannot be bypassed even by caffeinate.
  • 07.
    A ThoughtWorks engineer testing local models for coding found that task scoping is one of the biggest determinants of whether a small, locally-run model is viable at all, with small/pre-planned tasks working far better than open-ended ones.

Deep Analysis

The Privacy Promise Has an Asterisk

The pitch for local AI sounds airtight: if the model runs on your own hardware, nothing leaves the device, so there's nothing to collect. Mark McCreary, chair of the AI practice at Fox Rothschild, puts the appeal in its simplest form: "You've completely eliminated the risk of sending it to the company to process it." [6]That's a real and specific gain, and it's the gain Apple, Google, and a wave of startups like Hedy AI [9]are all racing to claim credit for as the privacy story of 2026.

But the lawyers working this space are more careful than the marketing. Brian Hengesbaugh, who chairs data privacy at Baker McKenzie, pushes back on the idea that local processing is a clean solution: "There's no magic answer or perfect answer to protecting privacy while using LLMs." [6]Alex Urbelis, general counsel at ENS Labs, goes further and flips the framing entirely, asking whether concentrating sensitive data onto a single personal device for an AI system to chew on actually creates a new target rather than removing one: "These AI systems may be great because we're localizing private data, but are they an attack vector?" [6]That question isn't rhetorical. Google's own response to prior Gemini assistant vulnerabilities, including lock-screen bypasses, was to ship 'AI seal,' a hardware-isolated secure vault for on-device AI workloads built on a pKVM hypervisor [3]- a direct admission that putting AI on the device opened a door that had to be bolted shut again. Apple is doing the same thing from the other direction, tightening macOS Full Disk Access controls specifically because locally-running AI agents now have a level of system reach that didn't exist before [7]. The privacy win is real, but it is narrower than 'your data never leaves your device' - it is 'your data isn't sent to a company's servers,' and that's a meaningfully smaller claim.
Friction, Not Capability, Is the Real Adoption Barrier

Every piece of hands-on reporting in this cluster converges on the same finding: the thing stopping ordinary people from running local AI isn't that the models are bad, it's that getting them running is a project. XDA's Samarveer Singh summarized the experience bluntly - "You have to become a researcher before becoming a user" [1]- after wrestling with quantization formats, VRAM limits, driver conflicts, and missing DLLs just to get a model to respond. He also names the psychological tax that friction imposes: "If something is free and local, part of your brain tends to automatically assume that it must be worse" [1], even when the underlying model is perfectly capable for the task at hand.

Thoughtworks' Birgitta Böckeler quantifies exactly how much hardware and task design matter: in her coding tests, an identical local-model configuration failed five of seven automated tests on a 48GB RAM machine but only one of seven on a 64GB machine [5]- the same model, wildly different outcomes, purely from memory headroom. Her broader conclusion is that task scoping, not model quality in the abstract, decides whether a small local model is viable at all. The same gap shows up on video: one widely watched demo proved a phone could run a model fully offline - Wi-Fi, mobile data, and airplane mode all switched off on-camera - with zero network dependency, framed explicitly as the privacy payoff. A separate hands-on test of a 9-billion-parameter open model reached the opposite caveat: it kept working with Wi-Fi off, but gave noticeably more 'watered-down generic' answers than a frontier cloud model on harder prompts, and going offline meant losing any cloud-dependent sync or sharing features. On Reddit, the same trade-off shows up in text: commenters running local setups through Ollama describe models like Qwen and Gemma as 'good enough' for narrow jobs - coding help, log parsing, scripting - but not competitive with frontier cloud models on harder reasoning, and still choose local because professionals in regulated fields treat privacy as non-negotiable rather than a trade-off.

Platforms Are Racing to Harden What They Just Shipped

Apple and Google are both building 2026 product strategy around on-device AI as a competitive differentiator, and the fight over whose silicon can carry the most AI locally is now a core battleground. Apple is making on-device AI a centerpiece of WWDC 2026, explicitly framing its years of custom-silicon investment as the reason it can process AI queries locally where cloud-dependent rivals can't [2], with trade press going so far as to call the move a 'privacy and security masterstroke' that sets Apple apart from cloud competitors [8].

That positioning is backed by hardware, not just messaging. Qualcomm and MediaTek are building their chips to support the same kind of hardware-isolation architecture Google just shipped as 'AI seal' [3], and by late 2026 flagship silicon from Apple, MediaTek, and Qualcomm had all converged on the 2nm process specifically to push more AI compute onto the device itself [12]. The 'edge' these companies are racing to own isn't just about running bigger models locally - it's a three-way bet that privacy-grade, hardware-isolated on-device processing becomes the default checkbox buyers look for, the way camera megapixels or battery life once were. Whoever gets there with the least user-facing friction - not necessarily the most raw model capability - stands to define what 'AI-first hardware' means for the next product cycle.

The Economics and Market Bet Behind the Shift

The on-device AI market is projected to grow from roughly $35.2 billion in 2026 to $191.7 billion by 2034, a 23.6% compound annual growth rate, with smartphones expected to account for 47.2% of that market this year [10]. That trajectory sits on top of nearly a decade of hardware groundwork - dedicated neural processing silicon has been doubling in smartphone performance roughly every year since Apple's A11 Bionic and Huawei's Kirin 970 NPU debuted in 2017 [11].

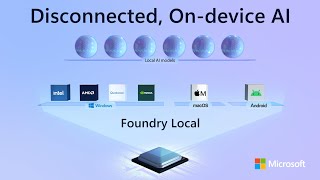
But the Reddit discourse around this cluster reveals a genuine fault line in why people actually adopt local AI: privacy versus pure economics. Several commenters argue local AI rarely beats a $20-a-month subscription on cost alone, and that the real case for going local rests on privacy, control, or hobbyist interest rather than dollars saved. Others frame it as insurance against future subscription price hikes once cloud providers need to turn a profit, pointing to how streaming and ride-share pricing crept upward over time as the cautionary comparison. Federico Viticci's experience on an M5 Ultra Mac Studio complicates both arguments: running a 125-billion-parameter model continuously via cloud APIs would be cost-prohibitive at his usage levels, which made a one-time hardware investment the more rational choice for a 24/7 personal-assistant workload [4]. That tension - privacy as the stated reason, economics as the quieter deciding factor - echoes in the broader conversation online, where enthusiasm about open on-device models catching up to frontier cloud quality is paired with major vendors like Microsoft framing their own local-model push not as a privacy mandate but as 'hybrid intelligence' - local processing invoked only with explicit user permission and only when it makes sense, suggesting the mainstream destination is a blended model, not a wholesale move off the cloud.

Historical Context

2011
Early on-device AI roots begin with Siri's local signal pre-processing on the A5 chip, even though core voice recognition ran in the cloud.
2017
Modern on-device AI era begins with Apple's A11 Bionic Neural Engine, Huawei's Kirin 970 NPU, and Google's TensorFlow Lite/NNAPI, kicking off yearly doubling of smartphone NPU performance.
2024-06
Apple unveiled 'Apple Intelligence' with on-device AI processing across phones, tablets, and computers; Microsoft followed with Copilot+ PCs that same year.
2026-09
Flagship smartphone chips (Apple A20 Pro, MediaTek Dimensity 9600 Pro, Qualcomm Snapdragon 8 Elite Gen 6) all moved to the 2nm process, each emphasizing stronger on-device AI capability.
2026-10-09
Google announced the 'AI seal' hardware-isolation feature for on-device AI on Android, addressing prior Gemini assistant vulnerabilities including lock-screen bypasses.

Power Map

Key Players
Subject

Rise of local, on-device AI for privacy

AP

Apple

Leveraging custom silicon to push on-device AI as a privacy differentiator versus cloud-dependent competitors; also tightening macOS privacy controls around AI agents' Full Disk Access.

GO

Google

Shipping 'AI seal,' a hardware-isolated secure vault for on-device AI workloads on Android, using the Android Virtualization Framework and a pKVM hypervisor certified at SESIP Assurance Level 5.

QU

Qualcomm / MediaTek

Chipmakers (Snapdragon, Dimensity 9600 Pro) supporting Google's hardware-isolation architecture and enabling flagship phones to run larger on-device models at the edge.

AN

Antonio Di Benedetto

Early-adopter reviewer documenting personal shift to local AI (Hermes agents, Qwen models) on Mac Studio/desktop and an Asus TUF A14 laptop, citing data-privacy motivation.

FE

Federico Viticci (MacStories)

Power user running Hermes Agent + a 125-billion-parameter Qwen model 24/7 for 99 days on an M5 Ultra Mac Studio as his default personal-assistant stack, citing cost and control benefits over cloud APIs.

SA

Samarveer Singh (XDA Developers)

Reviewer documenting hands-on friction (VRAM limits, week-long setup, driver issues) with self-hosting local LLMs on consumer hardware.

BI

Birgitta Böckeler (Thoughtworks)

Engineer evaluating local Qwen and Gemma models for coding tasks, documenting that task scoping and hardware RAM determine viability.

HE

Hedy AI

Vendor announcing a full on-device AI processing pipeline with no conversation data sent to remote servers, explicitly marketed as restoring privacy to AI tools.

Fact Check

12 cited
  1. [1] The Biggest Thing Holding Local AI Back Isn't Model Quality, It's Friction
  2. [2] Apple to Make On-Device AI Key Focus
  3. [3] Android On-Device AI Gets a Security Bump With Next-Gen Enclaves
  4. [4] M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents
  5. [5] Exploring Gen AI: Local Models for Coding Experiences
  6. [6] Big Tech Pushing On-Device AI as Privacy, Performance Booster
  7. [7] Apple Says It's Tightening macOS Privacy Controls Amid the Rise of AI Agents
  8. [8] Apple Doubles Down on On-Device AI in Privacy and Security Masterstroke That Sets It Apart From Cloud-Dependent Rivals
  9. [9] Hedy AI Launches On-Device AI Processing to Bring Privacy Back to AI Tools
  10. [10] On-Device AI Market Outlook & Market Share
  11. [11] On-Device AI
  12. [12] Smartphone AI Chip Design Comparison

Source Articles

Top 3

THE SIGNAL.

Analysts

“Describes a structural shift of AI compute from cloud to edge devices.”

Durga Malladi
SVP, Qualcomm Technologies

“Notes that on-device AI still faces hardware/memory constraints that limit how capable a local model can be.”

Frank Dickson
Market intelligence analyst, IDC

“Argues on-device processing removes a specific transmission risk, though not all privacy risk.”

Mark McCreary
Chair, AI Practice, Fox Rothschild

“Cautions that there is no single fix for LLM privacy risk even with local processing.”

Brian Hengesbaugh
Chair, Data Privacy, Baker McKenzie

“Raises concern that localizing private data for on-device AI could itself create a new attack surface.”

Alex Urbelis
General Counsel, ENS Labs

“Argues local AI's biggest barrier to mainstream adoption is friction (setup/model selection), not model quality, and that this friction gets unfairly read as a sign of inferiority.”

Samarveer Singh
Reviewer, XDA Developers

“Finds locally-run small models vastly underperform larger cloud models on agentic coding, but that careful task scoping and tech-stack choice can make them viable for narrow jobs.”

Birgitta Böckeler
Engineer, Thoughtworks
The Crowd

“Own your AI, don't let it own you — 6 months ago, the #1 AI was Claude Opus 4.6. Our model, Underdog 27B beats it while running on your Mac or iPhone. Most AI will run on your device, not in data centers.”

@@0xSigil1195

“Microsoft $MSFT CEO Satya Nadella just posted this: "We're supercharging Copilot on Windows with Hybrid Intelligence. With your permission, Copilot can tap into the context on your PC, take action for you, and use local models when it makes sense"”

@@StockMKTNewz249

“The State of Confidential AI — Every day, billions of prompts are sent to AI models, many carrying contracts, medical records, source code and private conversations. Almost every one of them is decrypted before the model can read...”

@@milianstx65

“I'm not paying $20 for ChatGPT or Claude because a free local LLM does everything I need”

@u/SoggyGrayDuck420
Broadcast
Run Offline AI on ANY Phone (Android & iPhone)

Run Offline AI on ANY Phone (Android & iPhone)

How To Run Open-Source AI Models on Your Phone (For Free)

How To Run Open-Source AI Models on Your Phone (For Free)

Run local AI on any PC or Mac - Microsoft Foundry Local

Run local AI on any PC or Mac - Microsoft Foundry Local