Mistral Large 4 'Le Chonk' launches in public preview, open weights due Oct 27
TECH

Mistral Large 4 'Le Chonk' launches in public preview, open weights due Oct 27

44+
Signals

Strategic Overview

  • 01.
    Mistral Large 4, nicknamed Le Chonk, launched in public preview on October 6, 2026 via Mistral's API, with open weights planned for October 27, 2026 after safety testing.
  • 02.
    The model was trained from scratch on roughly 3,800-4,000 Nvidia Grace Blackwell GPUs inside Mistral's own European data centers over about two months, on training data spanning more than 160 languages.
  • 03.
    Mistral's own official model listing states 675 billion total parameters with 41 billion active at inference, while Mistral's marketing and most secondary coverage cite roughly 1 trillion total and 49 billion active - a discrepancy flagged by independent analysis.
  • 04.
    Preview API pricing is listed at $1.36 per million input tokens and $4.18 per million output tokens, with a promotional 50%-off rate of $0.68/$2.09 during the preview window.

The Sovereignty Paradox: European AI Running on American Silicon

Mistral markets Le Chonk as proof that Europe can compete at the frontier without depending on American or Chinese AI infrastructure, but the model's own supply chain complicates that story. Training ran on roughly 3,800-4,000 Nvidia Grace Blackwell GPUs - American silicon from one of the world's dominant AI chipmakers - inside Mistral's European data centers over about two months[2], drawing on the order of 10 megawatts of power[12]. Nvidia's central role in the training stack sits awkwardly next to the sovereignty framing, and Mistral has been direct about the stakes, warning that Europe has roughly two years to build independent AI capability or risk becoming a vassal state to foreign providers[1]. Yet Le Chonk's own distribution leans on the same hyperscale infrastructure Mistral says Europe needs to escape - available today through Mistral's own API and third-party routers like OpenRouter, with the open-weight release expected to flow onto the same major cloud platforms (Azure, GCP, AWS) that host its rivals[3]. The paradox is not that Mistral trained on Nvidia hardware - nearly every lab does - but that a model positioned as a sovereignty milestone still depends entirely on non-European chips and non-European cloud rails to reach its users.
A Trillion Parameters or 675 Billion? The Spec Sheet Nobody Can Reconcile

Mistral's marketing materials and most secondary coverage describe Le Chonk as a 1 trillion parameter model with 49 billion active at inference, but Mistral's own official model listing states a smaller mixture-of-experts system: 675 billion total parameters with 41 billion active. Independent analysis from Shattered.io flagged the gap directly, noting that 'neither Mistral's announcement nor its model card, as captured in the official release, confirms those larger figures.'[4]The discrepancy matters because the circulated 1T figure has become shorthand for Le Chonk's scale in nearly every headline, even though the lab's own technical documentation does not support it. Guillaume Lample, Mistral's co-founder and chief scientist, still describes the model as being 'at the frontier of open weight models,'[5]but even Mistral's own framing admits the frontier claim does not hold evenly across domains - coding performance trails other frontier models[6], even as the model posts some of its strongest results in security and agentic benchmarks, suggesting the frontier label applies unevenly rather than across the board. For a model whose headline selling point is scale, the inability to get a straight answer on parameter count from the company that built it is itself a signal of how much of the Le Chonk launch is marketing versus documented spec.

Cheap Per Token, Expensive Per Task

Cheap Per Token, Expensive Per Task
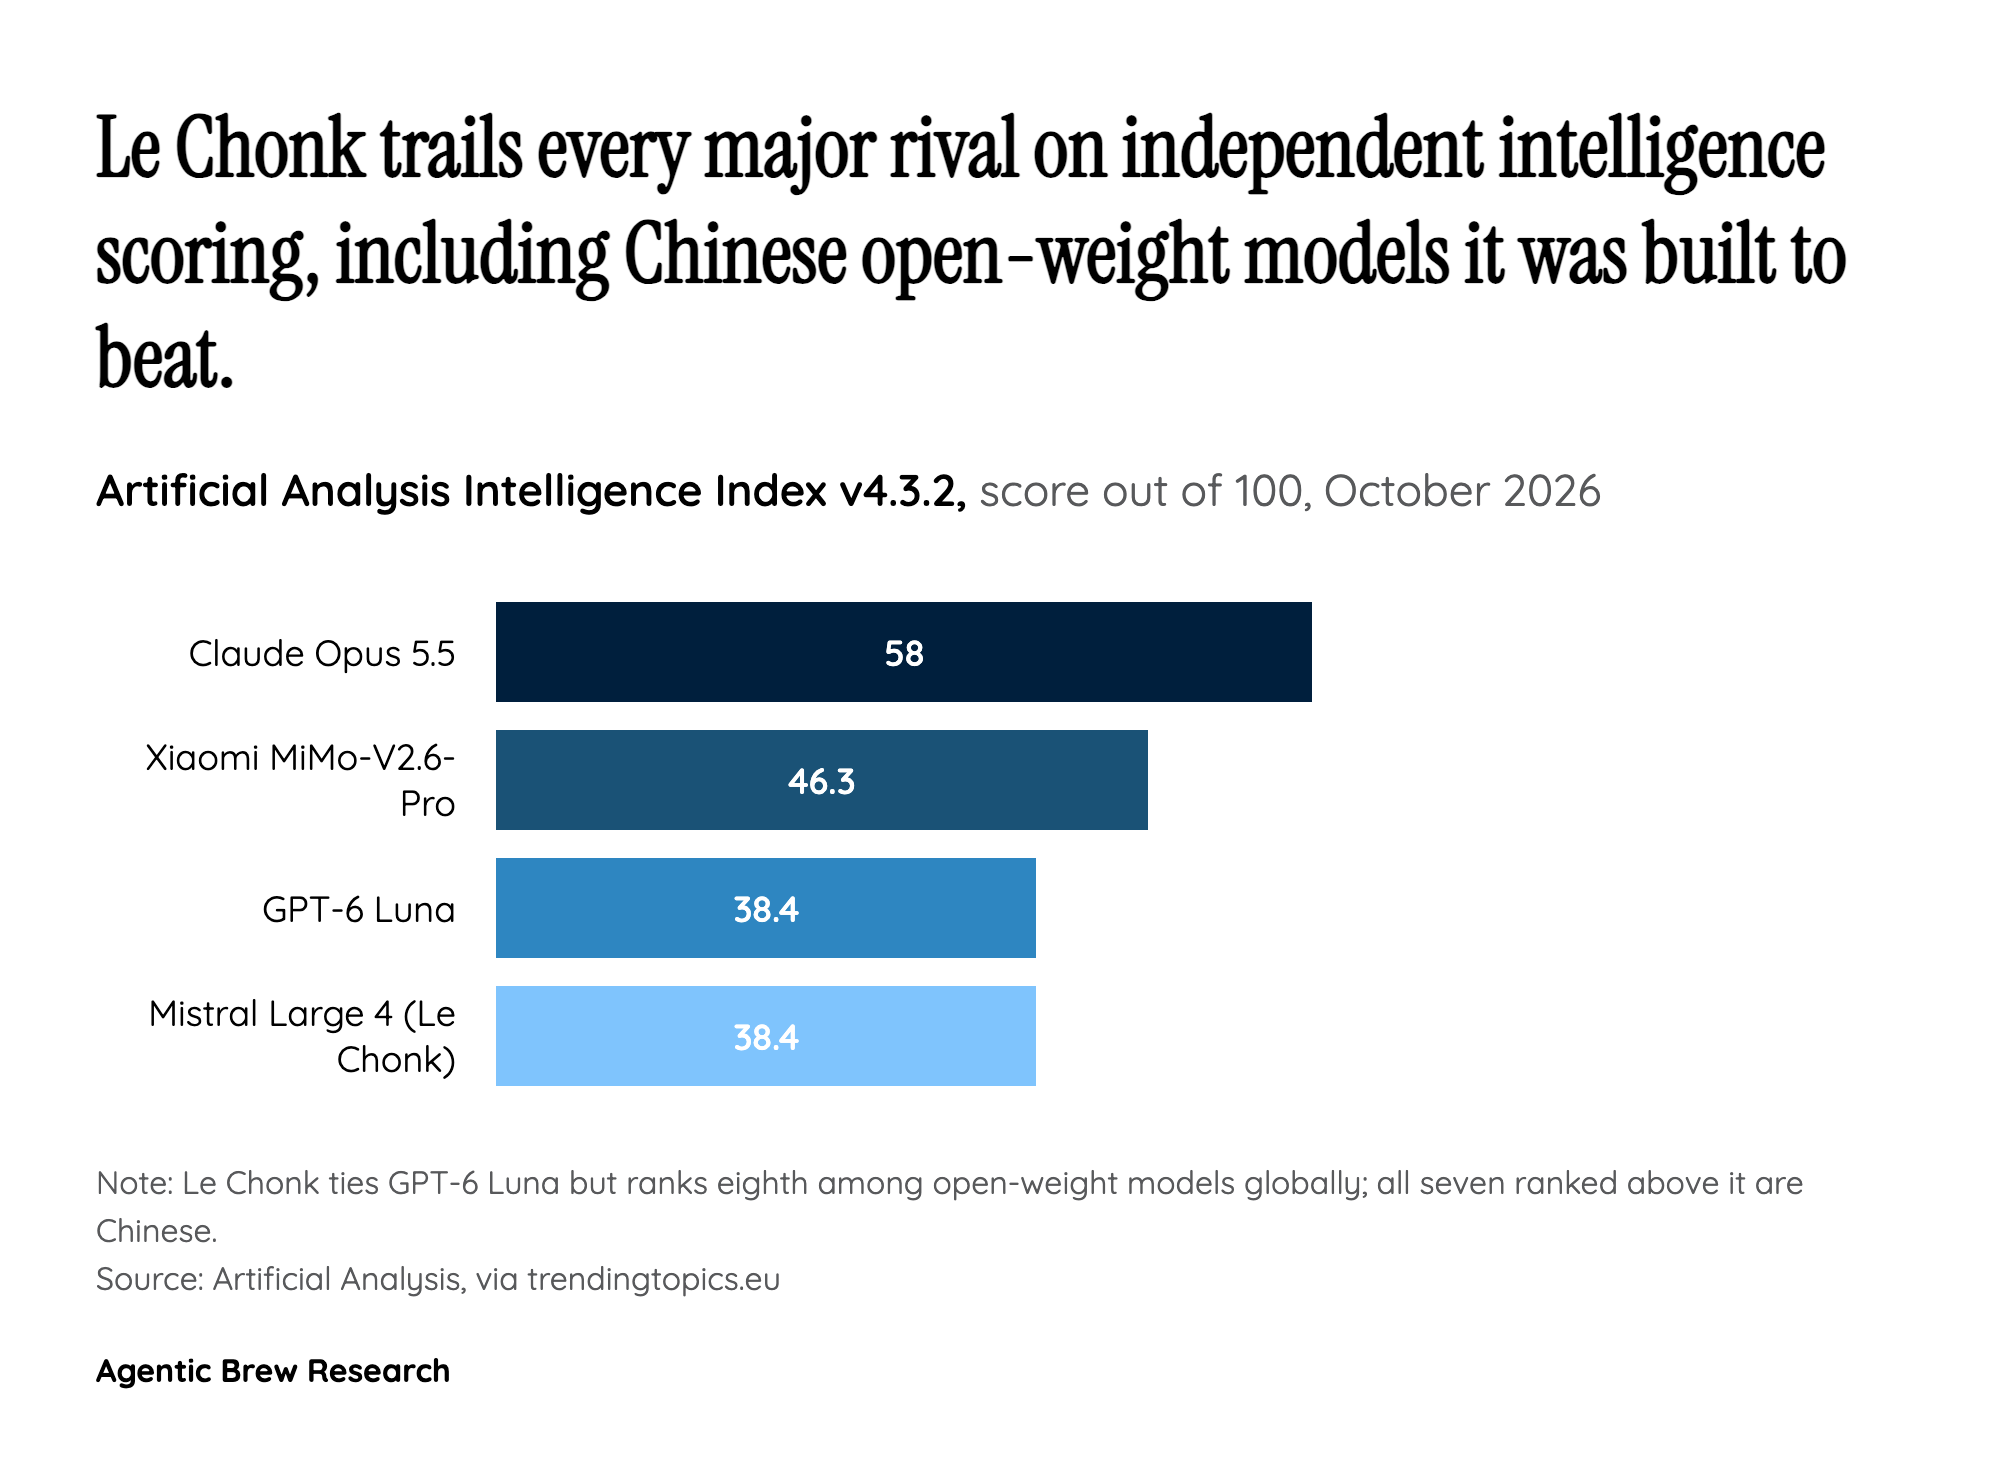
Le Chonk ties GPT-6 Luna on the Artificial Analysis Intelligence Index but ranks eighth among open-weight models globally, trailing all seven ranked Chinese models.

Le Chonk's advertised per-token pricing looks competitive: $1.36 per million input tokens and $4.18 per million output tokens on Mistral's own API, discounted 50% to $0.68/$2.09 during the preview window and matched on OpenRouter. But Artificial Analysis flagged the model as unusually verbose, generating roughly 200 million output tokens across its full benchmark suite versus a median of 81 million for comparable models[7]- meaning the token-level discount can be erased by how many tokens it takes to actually finish a task. The same complaint surfaced independently across Reddit's r/europe discussion and YouTube reviewer Robbert van Empel's hands-on test: Le Chonk's completed-task cost (reported around $1.13) ran roughly 16x higher than a comparable closed model's $0.07, even though the two scored almost identically on Artificial Analysis's Intelligence Index (38.4, tying GPT-6 Luna). For buyers comparing quoted per-token rates, that gap between cheap tokens and expensive tasks is the number that actually matters.

Where Le Chonk Actually Wins: Fewer Guardrails, Not Just More Capability

Mistral's own announcement leans on a specific set of benchmarks to make its enterprise case[2]. On Cybench, Le Chonk solved 93% of challenges, and on a vulnerability reproduction and patching test it hit 82%, the highest score of any model Mistral tested, with several closed models landing near zero. On the B3 Agent Security Benchmark, the model resisted 90-93.3% of prompt injection and adversarial attacks depending on the source cited. In coding, DeepSWE v1.1 put Le Chonk at 61.7-62%, ahead of GLM-5.3 (~61%), DeepSeek-V4-Pro (57%), and Reflection AI's newly launched Beam[10](44%). On finance, FinWorkBench scored it at 67%, tying DeepSeek-V4-Pro and ahead of GLM-5.3's 65%. On law, the Harvey Legal Agent Benchmark put it at 15-15.83%, ahead of Kimi K3 (13%) and GPT-6 Astra (5%), though still a low absolute score for a domain Mistral is marketing the model toward. Dignan's 'state-of-the-art on cybersecurity, finance and law' framing[9]and Mensch's cybersecurity claim against unspecified Chinese rivals[8]both point at this same cluster of numbers - the model's edge looks less like broad superiority and more like Mistral tuning hard for the specific agentic-security and enterprise-workflow tasks it expects to sell into, areas where several closed competitors post surprisingly weak scores.

Historical Context

2023
Founded by Arthur Mensch, Guillaume Lample, and Timothee Lacroix, former Google DeepMind and Meta researchers.
September 2025
Closed a 1.7 billion euro Series C led by ASML, reaching an 11.7 billion euro valuation.
December 2025
Released Mistral Large 3, the largest public model prior to Large 4, under an Apache 2.0 license.
September 8, 2026
Closed a 3 billion euro ($3.3 billion) Series D led by Samsung Electronics, with a post-money valuation above 21 billion euros, described as the largest-ever equity round by a European tech company.
October 5, 2026
Launched its own open-weight model, Beam (501B total / 23B active parameters), one day before Mistral's Large 4 preview, claiming competitiveness with 3-4x less compute.
October 6, 2026
Mensch unveiled Mistral Large 4 on stage at the Ai Everything conference in Abu Dhabi.

Power Map

Key Players
Subject

Mistral Large 4 'Le Chonk' launches in public preview, open weights due Oct 27

MI

Mistral AI

Developer and publisher of Mistral Large 4

AR

Arthur Mensch

CEO; unveiled Le Chonk on stage at the Ai Everything conference in Abu Dhabi and claimed it beats unspecified Chinese rivals on cybersecurity

GU

Guillaume Lample

Co-founder and chief scientist; positioned the model as at the frontier of open-weight models

NV

Nvidia

GPU supplier (Grace Blackwell) underlying all of Le Chonk's training compute

RE

Reflection AI

Competing lab that launched its own open-weight model, Beam, one day before Le Chonk's preview

AR

Artificial Analysis

Independent benchmarking firm whose ranking (eighth among open-weight models globally) shapes how the market reads Mistral's claims

Fact Check

12 cited
  1. [1] Mistral's AI Leadership a Threat to European Sovereign Tech
  2. [2] Introducing Mistral Large 4
  3. [3] Mistral Large 4 Sovereign AI Open Weight Model
  4. [4] Mistral Large 4 Parameter Count Gap
  5. [5] Mistral Debuts Large 4 'Le Chonk'
  6. [6] Mistral Large 4 Preview Coverage
  7. [7] Mistral Large 4 Artificial Analysis Ranking
  8. [8] Mistral CEO Cybersecurity Claim vs Chinese Rivals
  9. [9] Mistral Makes Its Open Model Case
  10. [10] Reflection AI Beam 4x Less Compute
  11. [11] Mistral Launches Large 4 Preview with 1T Parameters
  12. [12] Mistral Large 4 Le Chonk 1T Open Weights Preview

Source Articles

Top 5

THE SIGNAL.

Analysts

“With 38.4 points on the Intelligence Index, Large 4 is a huge leap over its predecessors - Mistral Medium 3.5 scored 14 and Large 3 scored 9 - but it still ranks eighth among open-weight models globally, with all seven ahead of it Chinese, led by Xiaomi's MiMo-V2.6-Pro at 46.3. The firm also flagged the model as 'very verbose,' generating roughly 200 million output tokens across the full benchmark index versus a median of 81 million.”

Artificial Analysis
Le Chonk is a real leap for Mistral but still trails Chinese open-weight leaders and runs unusually verbose

“On critical enterprise workloads, including cybersecurity, finance and law, we find it to be state-of-the-art.”

Larry Dignan, Constellation Research
A credible enterprise alternative on critical workloads

“ML4 is at the frontier of open weight models.”

Guillaume Lample
Le Chonk represents Mistral's strongest open-weight claim to date

“Neither Mistral's announcement nor its model card, as captured in the official release, confirms those larger figures. The French lab's own model listing puts the mixture-of-experts system at 675 billion total parameters with 41 billion active at inference time.”

Shattered.io analysis
Enterprise teams should trust Mistral's own model card over widely repeated marketing figures
The Crowd

“Meet Mistral Large 4, aka Le Chonk. • 1T parameters, natively multimodal. 49B active. It is the best open weights model from US or Europe on aggregated benchmarks. • State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses”

@@MistralAI36010

“Excited”

@@arthurmensch3217

“Le Chonk has arrived 🐈 Mistral Large 4 is now on OpenRouter in public preview: 1T params (49B active), natively multimodal, 1M context, up to 256K output. 50% off for the first two weeks: $0.68 in / $2.09 out per 1M tokens ($0.07 cached).”

@@OpenRouter1026

“Introducing Mistral Large 4”

@u/pc0999914
Broadcast
Mistral Is BACK – Mistral Large 4 First Test (Le Chonk!)

Mistral Is BACK – Mistral Large 4 First Test (Le Chonk!)

Mistral is BACK! (Le Chonk)

Mistral is BACK! (Le Chonk)

Mistral Large 4 Tested: Is Europe's New AI Worth the Cost?

Mistral Large 4 Tested: Is Europe's New AI Worth the Cost?

Mistral Large 4 'Le Chonk' launches in public preview, open weights due Oct 27 — AI News | Agentic Brew