A Pareto Improvement: Same Price, Sharper Unit Economics
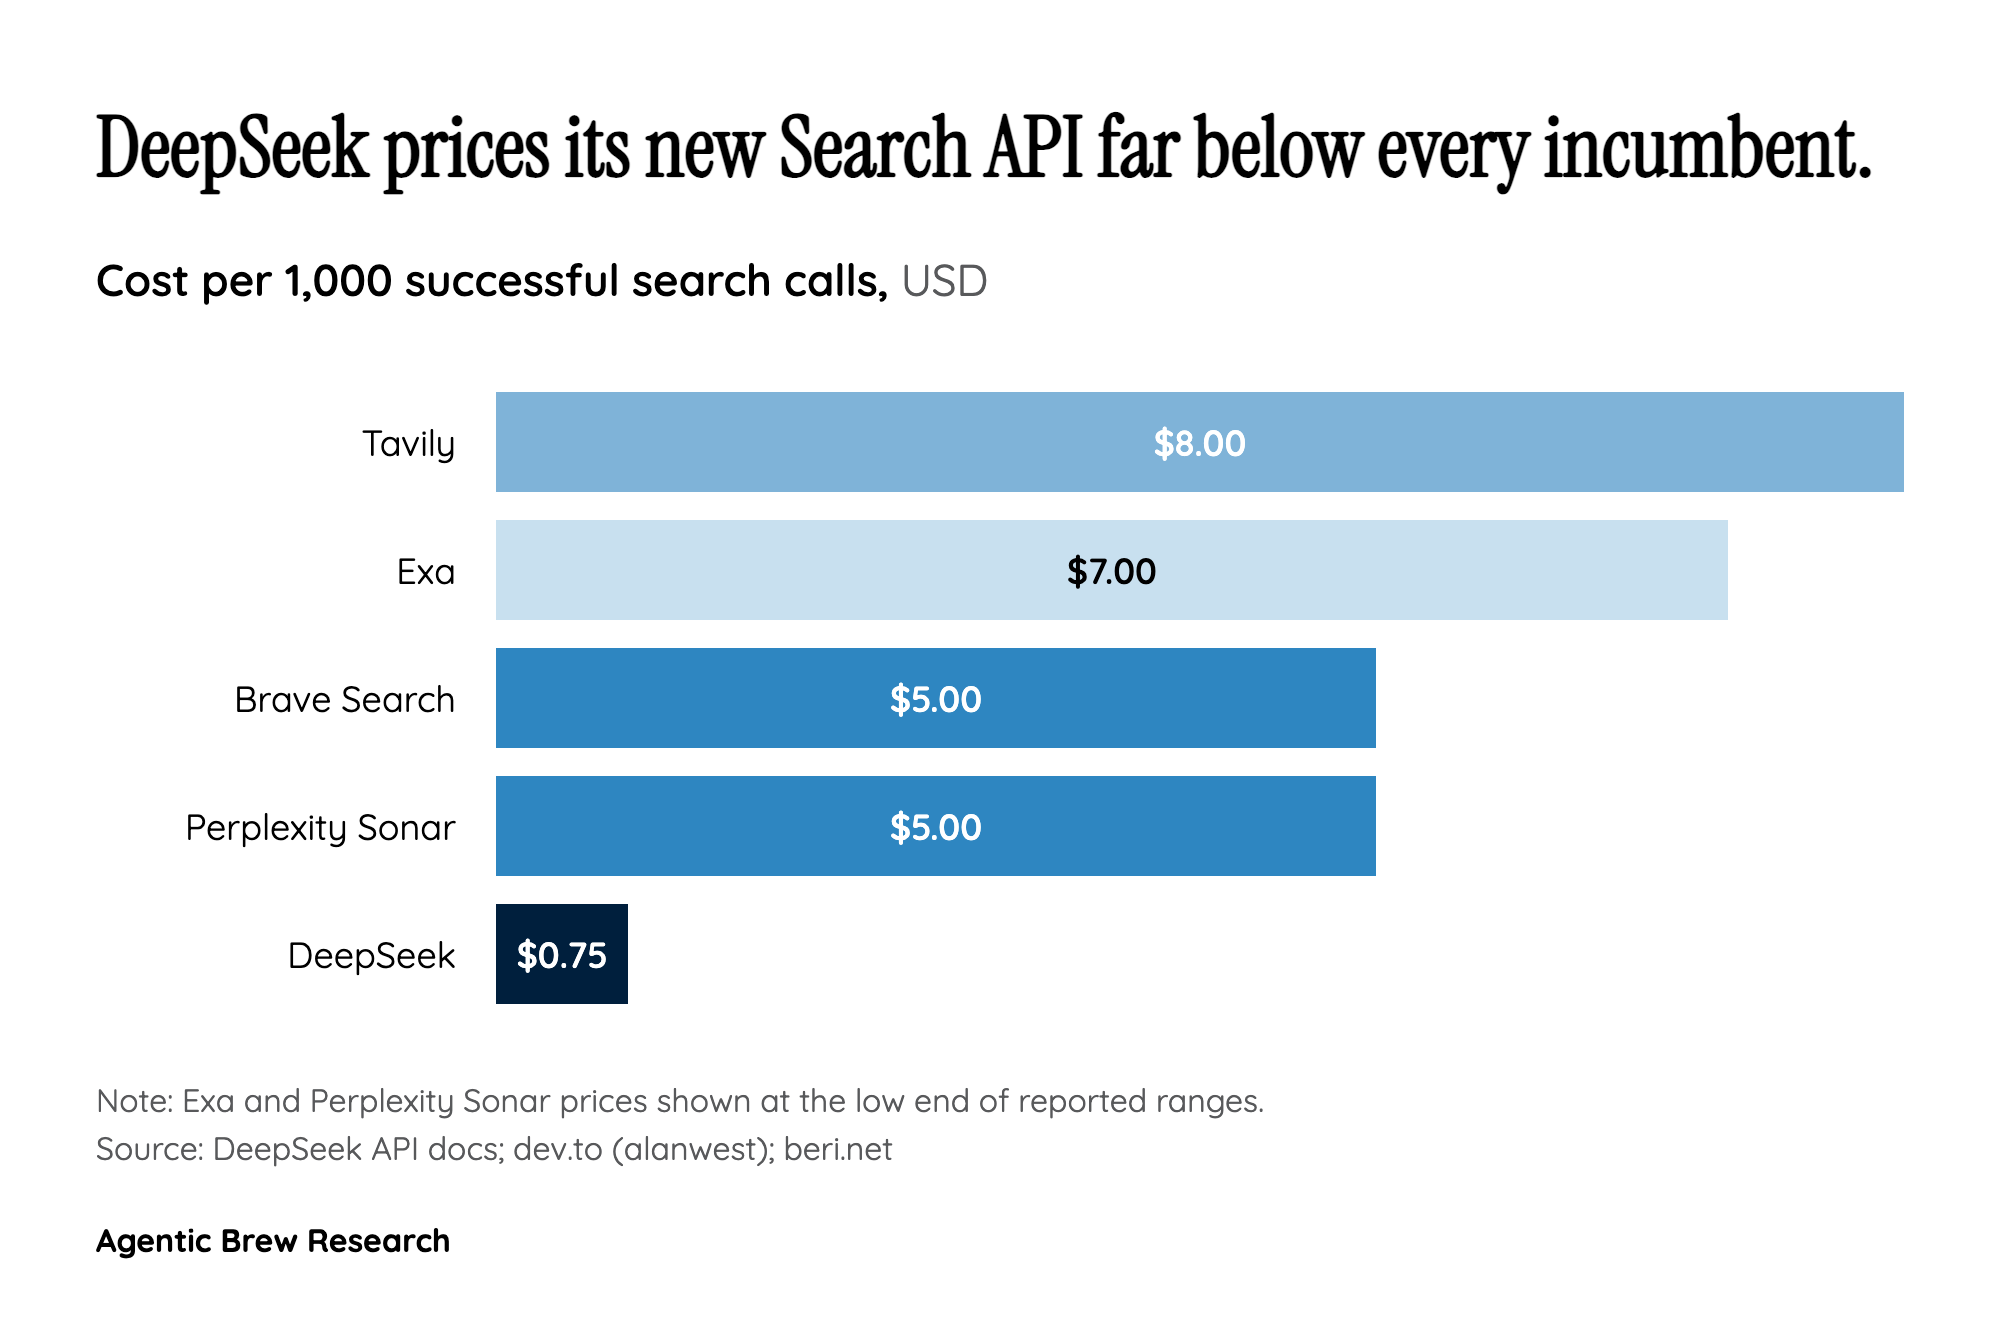
DeepSeek's October 17 post-training refresh of V4.1-Flash beat the September build on all 11 benchmarks it reported, with gains ranging from 2.0 to 11.1 points [4]. The agentic-coding numbers moved the most: DeepSWE v1.1 climbed from 74.2% to 77.0%, edging past Claude Opus 5 (74.0%) and GPT 5.6-Sol (73.0%) [2], while Terminal-Bench 4.0 jumped from 31.2 to 42.3 [4]. None of this required a price increase: DeepSeek kept the deepseek-flash model ID and existing per-token rates, with the 1017 build simply writing fewer output tokens per completed task [1][14]. That token discipline is what makes this a genuine Pareto improvement rather than a marketing refresh - DeepSeek's own numbers put the cost of a finished DeepSWE task at roughly $0.20, down from about $0.50 on the September build, with a leaner $0.10-per-task mode available at a 72% accuracy tradeoff [3]. The release is described as reinforcement learning with self-feedback (RLSF) applied to the existing checkpoint rather than a full retrain [3]- a cheaper way to buy benchmark headroom than training a new base model from scratch.